Introduction: The Silent Backbone of Carrier-Grade Infrastructure
In the hyper-competitive landscape of modern telecommunications, the difference between a 99.999% availability SLA and a catastrophic outage often lies not in the fiber optic cables themselves, but in the invisible layer of intelligence governing them: Telecom Network Inventory Management (TNIM). As a Senior Network Architect with 15 years of Tier-1 carrier experience, I have witnessed the evolution from manual spreadsheets to AI-driven, real-time discovery engines. This definitive guide dissects the architectural imperatives, hardware specifications, and deployment strategies essential for managing network assets at scale.
According to ITU-T recommendations (specifically M.3400 series), effective inventory management is no longer a passive record-keeping function. It is an active, dynamic control plane that must correlate physical layer components (transceivers, chassis, line cards) with logical service layers (VLANs, MPLS LSPs, VPN instances). A failure to synchronize these layers results in configuration drift, a leading cause of the 23% of network outages attributed to human error in manual audits.
Core Architecture & Hardware Topology
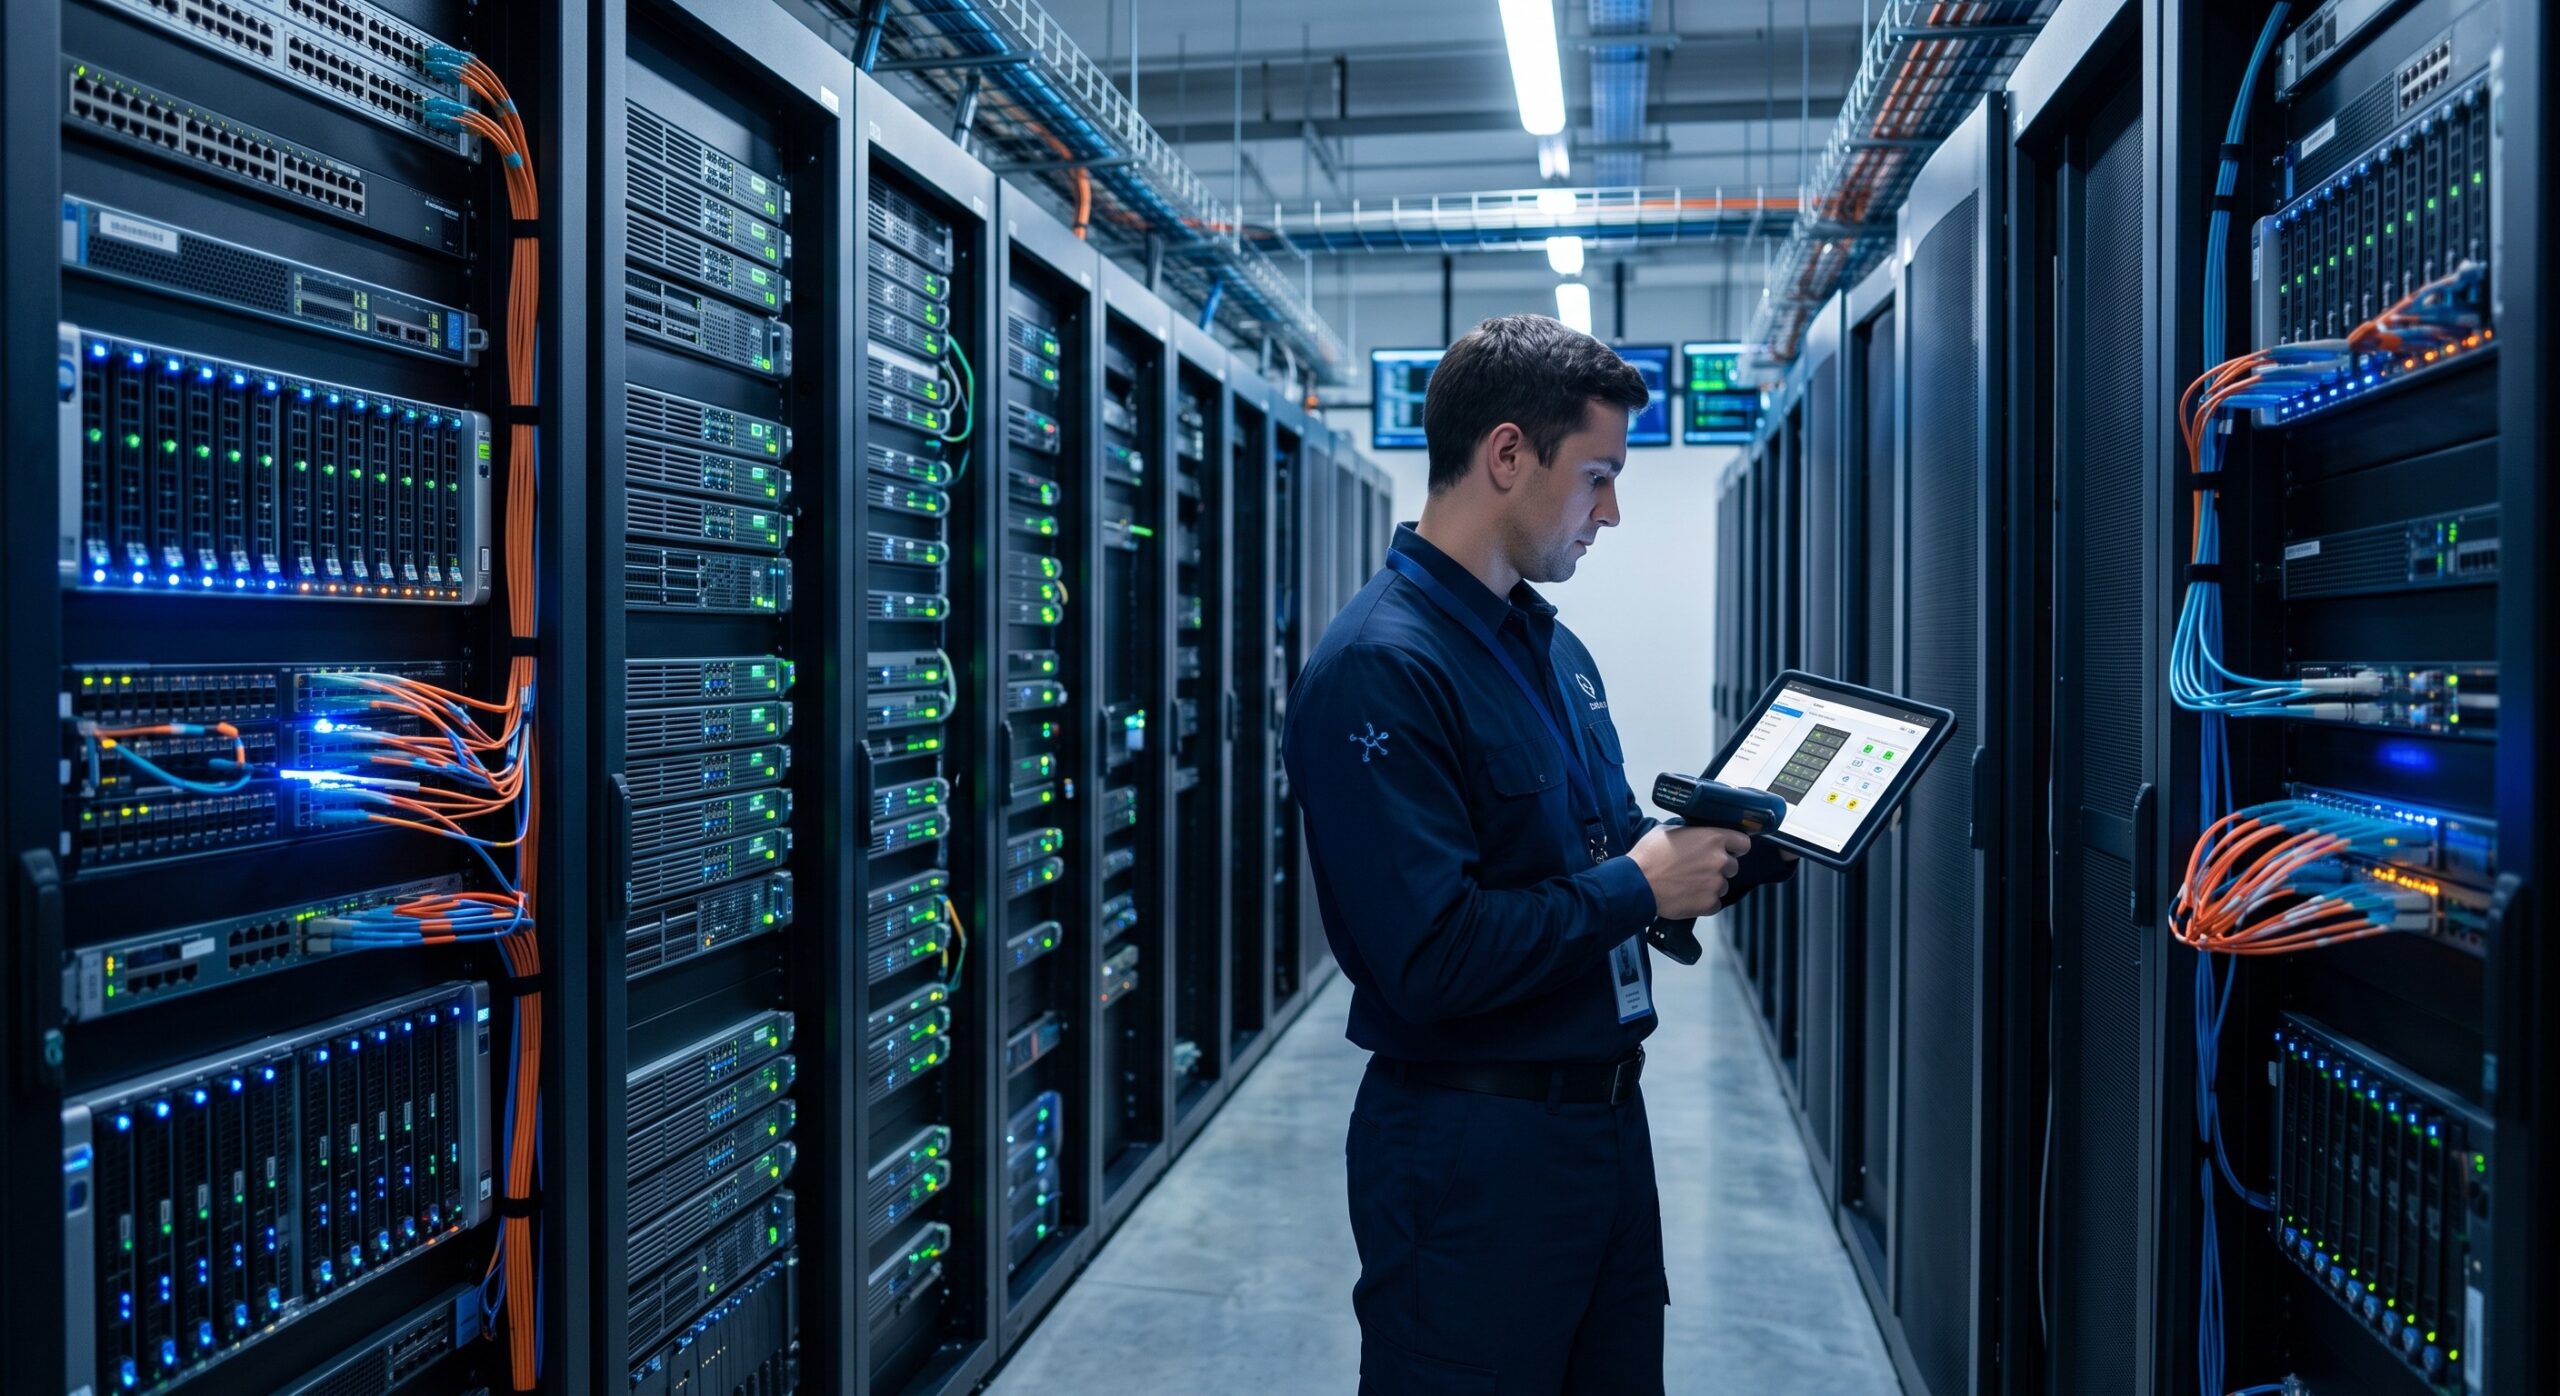
A robust TNIM system relies on a distributed microservices architecture that must handle millions of data points per second. The hardware topology is typically divided into three functional planes: the Discovery Plane, the Data Persistence Layer, and the Reconciliation Engine.
The Discovery Plane: Active vs. Passive Probing
Modern inventory systems utilize a hybrid approach. Active discovery employs SNMPv3 (Simple Network Management Protocol) and NETCONF/YANG to poll devices at regular intervals. For high-density core routers, the polling frequency must be balanced against CPU load; a standard recommendation is a 5-minute interval for interface counters and a 15-minute interval for chassis inventory (serial numbers, firmware versions, MAC address tables). Passive discovery relies on sFlow or IPFIX to capture traffic metadata, providing real-time visibility into traffic flows without overloading the management plane.
The Data Persistence Layer: Graph Databases vs. Relational
Legacy systems utilized relational databases (RDBMS), which struggle with the recursive relationships inherent in network topologies. Modern TNIM deployments are migrating to Graph Databases (e.g., Neo4j) to represent nodes and edges efficiently. This allows for complex queries such as “show me all 100Gbps ports on this chassis that are connected to a device with a firmware vulnerability.” The hardware hosting this layer typically requires NVMe SSD storage with high IOPS (Input/Output Operations Per Second) and ECC memory to ensure data integrity.
| Key Parameter | Technical Specification |
|---|---|
| Switching Capacity | Up to 25.6 Tbps (per chassis) |
| Port Density | 48 x 400G QSFP-DD or 144 x 100G QSFP28 |
| Latency (Store-and-Forward) | |
| MTBF | > 100,000 hours (controller hardware) |
| Protocol Support | SNMPv3, NETCONF/YANG, LLDP (IEEE 802.1AB) |
| Power Consumption | Typical 12kW per fully loaded chassis (RoHS compliant) |
Logic Layer Deep Dive: The Reconciliation Engine
The most critical component of TNIM is the reconciliation engine, which compares the “As-Built” (physical reality) against the “As-Designed” (intended configuration). This process is governed by IEEE 802.1AB (Link Layer Discovery Protocol – LLDP) for neighbor discovery and IEEE 802.3ad (Link Aggregation) for port channel verification. When a discrepancy is detected—such as a missing SFP+ module or an incorrect MTU setting—the system must trigger an alert via Syslog or TACACS+.
Performance Metrics and Latency Considerations
In carrier-grade networks, the inventory management system itself must not introduce latency into the control plane. The polling engine must operate with a sub-millisecond internal processing latency. For large-scale ISPs managing over 50,000 nodes, the system must handle 10,000+ concurrent sessions during peak discovery cycles. The MTBF (Mean Time Between Failures) for the hardware hosting the TNIM controller should exceed 100,000 hours, often achieved through redundant power supplies and hot-swappable fan trays.
Integration with OSS/BSS Ecosystems
TNIM does not operate in a vacuum. It must integrate with OSS (Operational Support Systems) for fault management and BSS (Business Support Systems) for billing. This integration is typically achieved via RESTful APIs or Kafka message queues. The data model must adhere to the TMF SID (Shared Information/Data Model) to ensure interoperability. Failure to standardize this data leads to “swivel-chair” operations, increasing OpEx by up to 30%.
Benchmark vs Legacy: The Shift from Manual to Automated
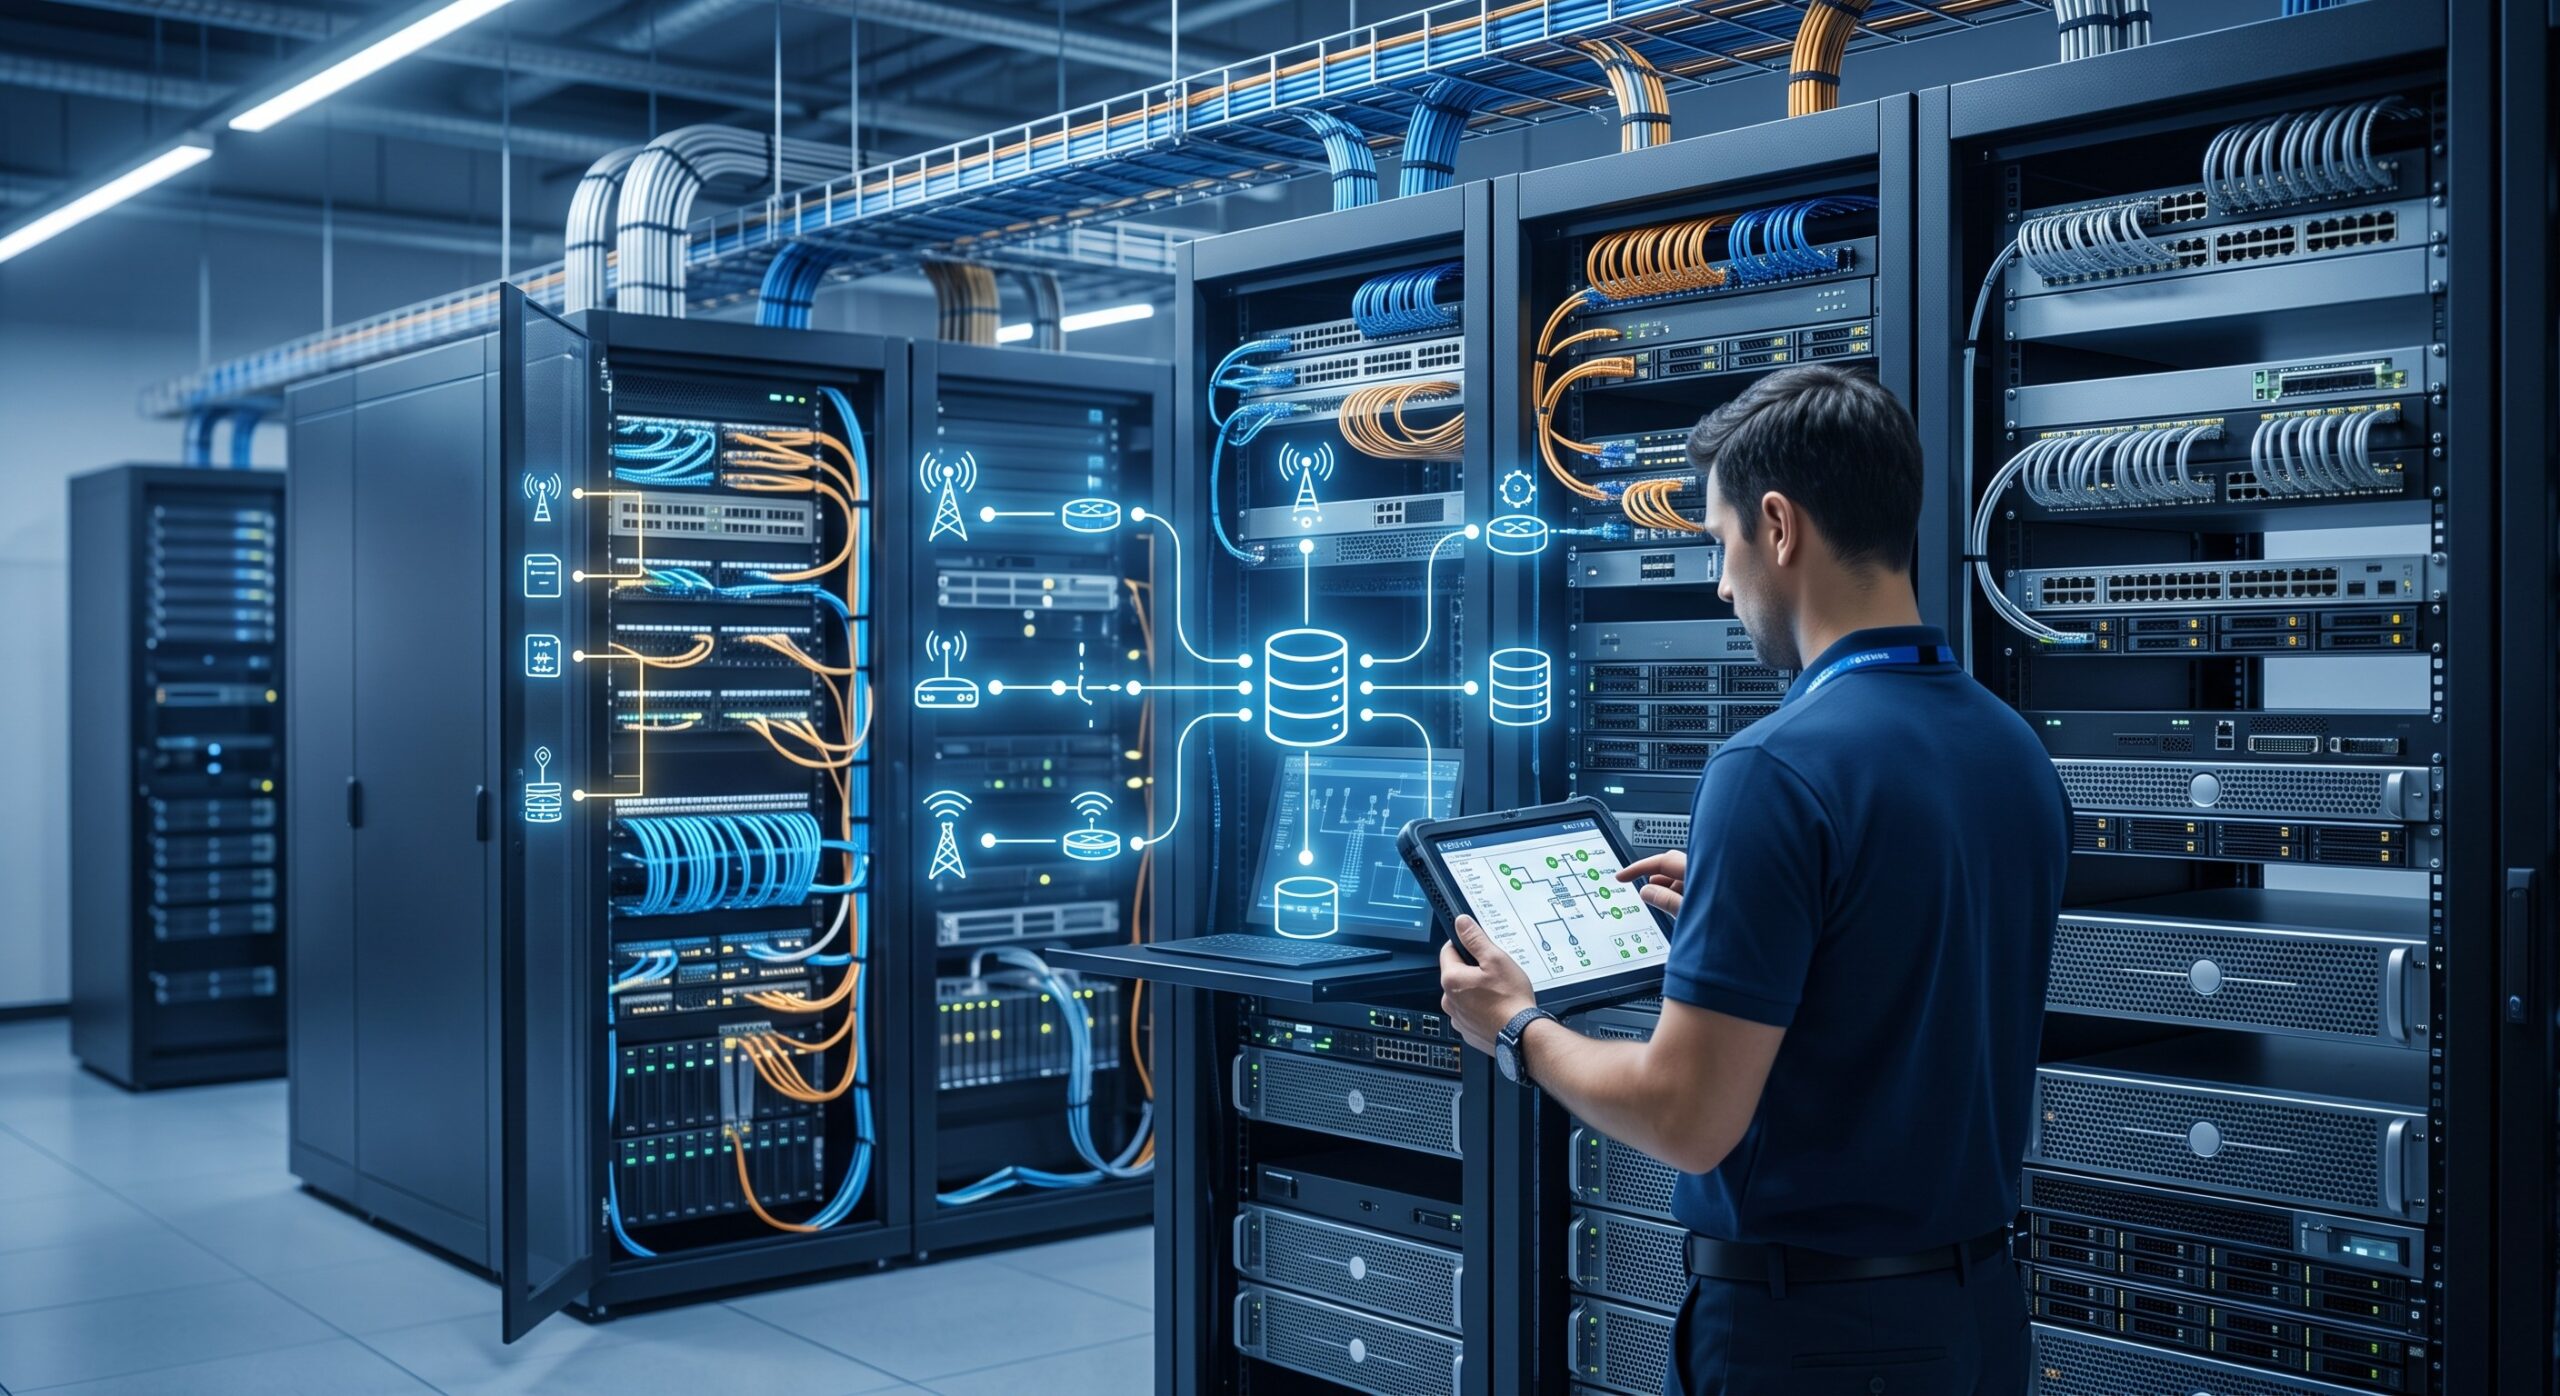
Comparing a modern automated TNIM against a legacy spreadsheet-based approach reveals stark operational differences:
- Audit Time: Legacy manual audits take approximately 40 man-hours per 100 devices. Automated systems complete this in under 5 minutes with 99.9% accuracy.
- Mean Time to Repair (MTTR): Automated topology mapping reduces MTTR by 45% by instantly identifying the affected service path and upstream dependencies.
- CapEx Optimization: By identifying unused ports and “zombie” assets, automated TNIM can reclaim up to 15% of deployed hardware, deferring capital expenditure on new line cards.
ISP Case Study: Scaling to 400Gbps with Zero-Touch Provisioning
A Tier-2 ISP in the EMEA region recently migrated from a legacy RDBMS to a graph-based TNIM solution. The goal was to support a new 400Gbps core ring while maintaining RoHS compliance and reducing energy consumption. By implementing Zero-Touch Provisioning (ZTP) workflows, the ISP reduced device onboarding time from 4 hours to 12 minutes. The TNIM system automatically validated OSFP transceiver compatibility and FEC (Forward Error Correction) settings against ITU-T G.709 standards. The result was a 99.999% service availability record for six consecutive quarters and a 22% reduction in truck rolls for physical audits.
Conclusion: The Strategic Imperative
Telecom Network Inventory Management is not merely a database; it is the single source of truth that enables agility, reduces OpEx, and ensures compliance in an increasingly complex regulatory environment. As networks converge toward 5G and SDN/NFV architectures, the inventory system must evolve from a passive observer to an active participant in network orchestration. Investing in a scalable, standards-compliant TNIM architecture is not an IT expense—it is a strategic imperative for any operator serious about carrier-grade reliability.
Leave a comment