Introduction: The Interconnect Imperative in Heterogeneous AI Computing
The exponential growth of large language models (LLMs) and real-time inference workloads has fundamentally shifted the datacenter hardware paradigm. Modern telecom edge AI nodes and core datacenter AI accelerator modules no longer operate in isolation. They are part of a heterogeneous computing fabric where CPUs, GPUs, NPUs, and custom ASICs must communicate with deterministic latency and massive bandwidth. The choice of interconnect protocol—whether CXL (Compute Express Link) or a proprietary link—directly dictates system scalability, deployment flexibility, and total cost of ownership. This guide provides a definitive architectural, specification, and deployment analysis for network architects and telecom hardware engineers evaluating these competing interconnect strategies.
Core Architecture and Hardware Topology: CXL vs Proprietary Link Fabrics
Understanding the Physical and Logic Layer Divide
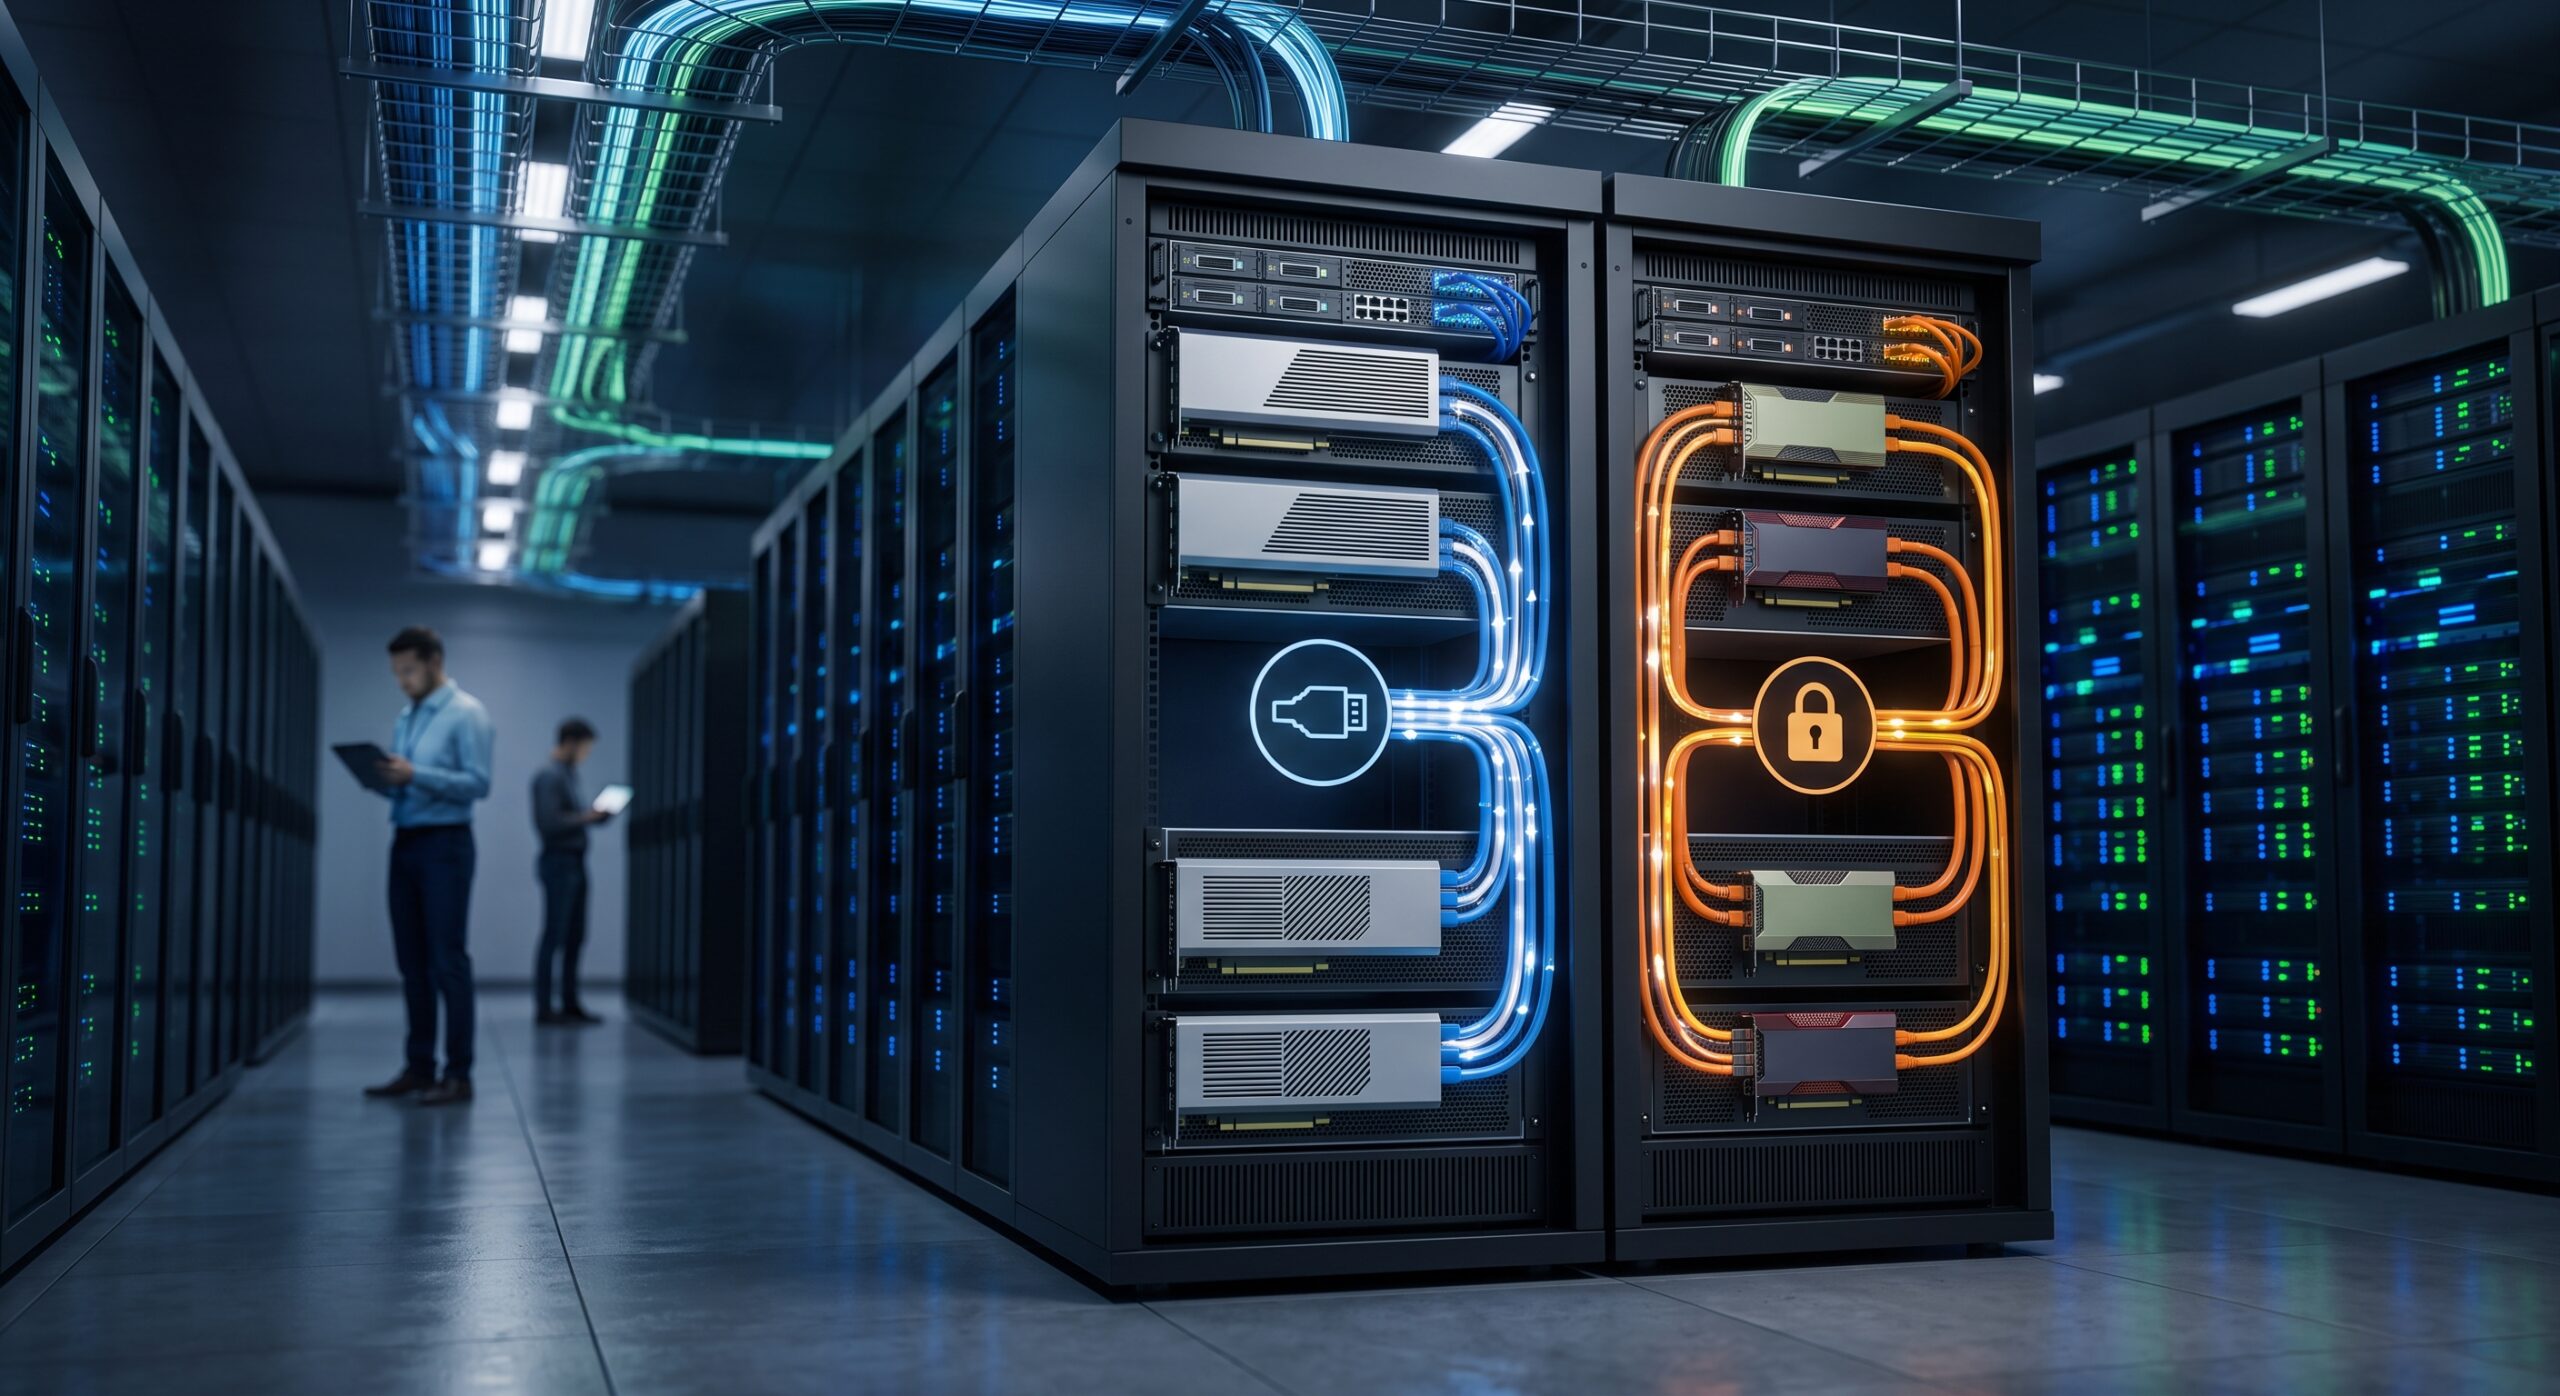
CXL is an open industry-standard interconnect built upon the PCIe 5.0/6.0 physical layer, utilizing a flexible protocol multiplexer to support three sub-protocols: CXL.io for discovery and configuration, CXL.cache for device coherency, and CXL.mem for host-managed device memory. This enables memory semantic communication critical for AI accelerator pooling. In contrast, proprietary links—such as NVIDIA’s NVLink, AMD’s Infinity Fabric, or custom die-to-die (D2D) interconnects—are optimized for specific silicon ecosystems. They often employ wide, parallel lanes and custom forwarding logic to achieve lower per-hop latency but lack multi-vendor interoperability. The hardware topology for CXL typically involves a root complex with switched fabric supporting up to 16 lanes per link, while proprietary links frequently use serializer/deserializer (SerDes) lanes running at 50G PAM4 or higher per lane.
ASIC Logic and Forwarding Engine Design
The internal ASIC logic for CXL requires a cache coherency engine and a memory translation agent (such as a Home Agent) to maintain data consistency across CPU and accelerator domains. Proprietary links often bypass coherency overhead by using explicit DMA and doorbell registers, trading programmability for raw throughput. For telecom AI workloads, this means CXL excels in memory disaggregation and accelerator pooling, while proprietary links dominate in tightly coupled training clusters.
| Key Parameter | CXL 3.0 Specification | Proprietary Link (Typical 600 GB/s) |
|---|---|---|
| Raw Bandwidth (x16) | 256 GB/s bidirectional | 600-900 GB/s bidirectional |
| Per-Lane Speed | 64 GT/s (PAM4) | 50-112 Gbps (PAM4/NRZ) |
| Protocol Latency (Typical) | 70-90 ns | 35-50 ns |
| Coherency Support | Native (CXL.cache / CXL.mem) | Explicit DMA / Doorbell |
| Multi-Vendor Interop | Yes (CXL Consortium) | No (Vendor Locked) |
| Energy Efficiency | 1.8 pJ/bit | 1.2 pJ/bit |
| MTBF (Switch ASIC) | 1.2 million hours | 0.8-1.5 million hours |
| Compliance Standards | IEEE 802.3, CXL 3.0, RoHS | Proprietary, ITU-T thermal |
Benchmark vs Legacy: Performance, Latency, and Efficiency Metrics
Data-Driven Comparison of Interconnect Protocols
When evaluating CXL 3.0 against a typical proprietary 600 GB/s link, the trade-offs become clear. CXL 3.0 supports 64 GT/s per lane (PCIe 6.0 signaling) with PAM4 encoding, delivering up to 256 GB/s bidirectional on a x16 link. However, protocol overhead for coherency and flow control introduces 70-90 ns of latency. Proprietary links, such as NVLink 4.0, achieve 900 GB/s bidirectional with sub-50 ns latency but require proprietary switch ASICs and vendor-locked topologies. In terms of energy efficiency, CXL demonstrates 1.8 pJ/bit for short-reach copper, while proprietary links can reach 1.2 pJ/bit using optimized SerDes and equalization. For carrier-grade telecom deployments, MTBF for CXL switches is typically 1.2 million hours, whereas proprietary fabric switches range from 800,000 to 1.5 million hours depending on thermal design.
Case Study: ISP Edge AI Inference Cluster
A tier-1 ISP deployed a heterogeneous AI inference cluster for real-time video analytics at the edge. Using CXL memory pooling, they reduced GPU idle time by 34% and lowered DRAM cost per node by 22%. However, they observed coherency stalls under bursty traffic. By integrating a proprietary low-latency link between NPU pairs for packet preprocessing, they achieved end-to-end latency of 1.8 ms for video frame inference. This hybrid approach—CXL for memory, proprietary for compute-to-compute—is becoming a best practice in telecom AI infrastructure.
Conclusion: Strategic Interconnect Selection for Future-Proof Telecom AI
The decision between CXL and proprietary links is not binary. CXL offers open standards, memory coherency, and multi-vendor flexibility, making it ideal for disaggregated AI inference and edge cloud deployments. Proprietary links deliver maximum bandwidth, lowest latency, and tight ecosystem integration, suited for training clusters and carrier-grade core AI routing. Network architects should adopt a hybrid interconnect strategy, leveraging CXL for memory pooling and proprietary links for high-speed accelerator meshes. As IEEE 802.3 and CXL Consortium evolve standards, expect converged protocols that blend coherency with raw speed. Compliance with RoHS and ITU-T thermal guidelines remains mandatory for telecom-grade hardware. The future belongs to adaptive, software-defined interconnect fabrics that dynamically route AI traffic across heterogeneous compute elements.
Leave a comment