
SLA Demands in Modern DDoS Mitigation Architectures
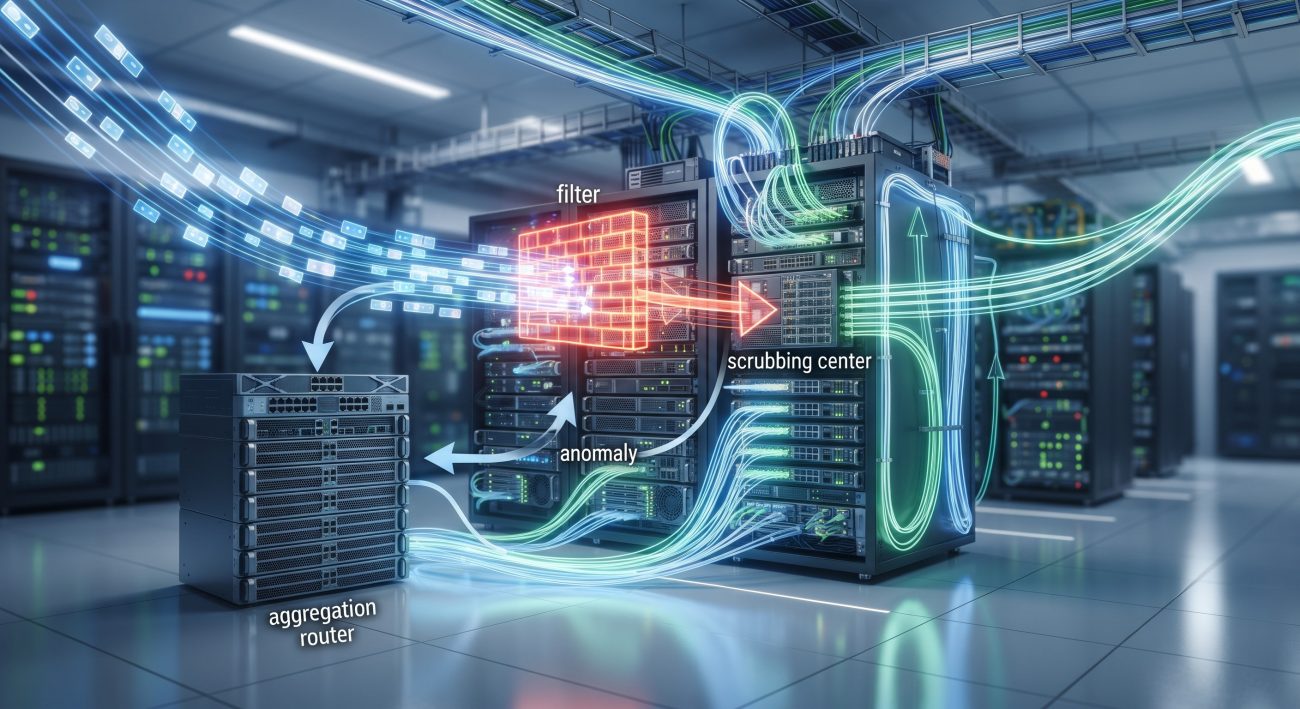
Enterprise and carrier networks face a relentless escalation in DDoS attack volume and frequency, with modern volumetric attacks routinely exceeding 1 Tbps and complex multi-vector attacks targeting application-layer state exhaustion. Legacy mitigation approaches like Remotely Triggered Black Hole (RTBH) routing offer binary outcomes: either the target IP remains online and vulnerable, or it is completely withdrawn, violating even the most permissive Service Level Agreements (SLAs). The operational mandate for BGP Flowspec (RFC 5575) arises from this gap—delivering surgical, line-rate traffic filtering that preserves legitimate business flows while dropping attack vectors at the forwarding plane.
For the Senior Network Architect, the decision to deploy Flowspec at the edge is not merely a feature toggle; it is a reliability engineering challenge. The Mean Time Between Failures (MTBF) of the mitigation pipeline must exceed the attack duration curve. If the Flowspec controller or the Route Reflector (RR) hierarchy fails during a sustained 400 Gbps SYN flood, the edge routers must fail open or hold state without inducing a control-plane storm. This analysis evaluates the redundancy mechanisms, hardware ASIC dependencies, and carrier-grade MTBF metrics essential for automated scrubbing at the network periphery.
Dual-Engine Failover Architecture for Flowspec Injection
Controller Redundancy and BGP Session Resiliency
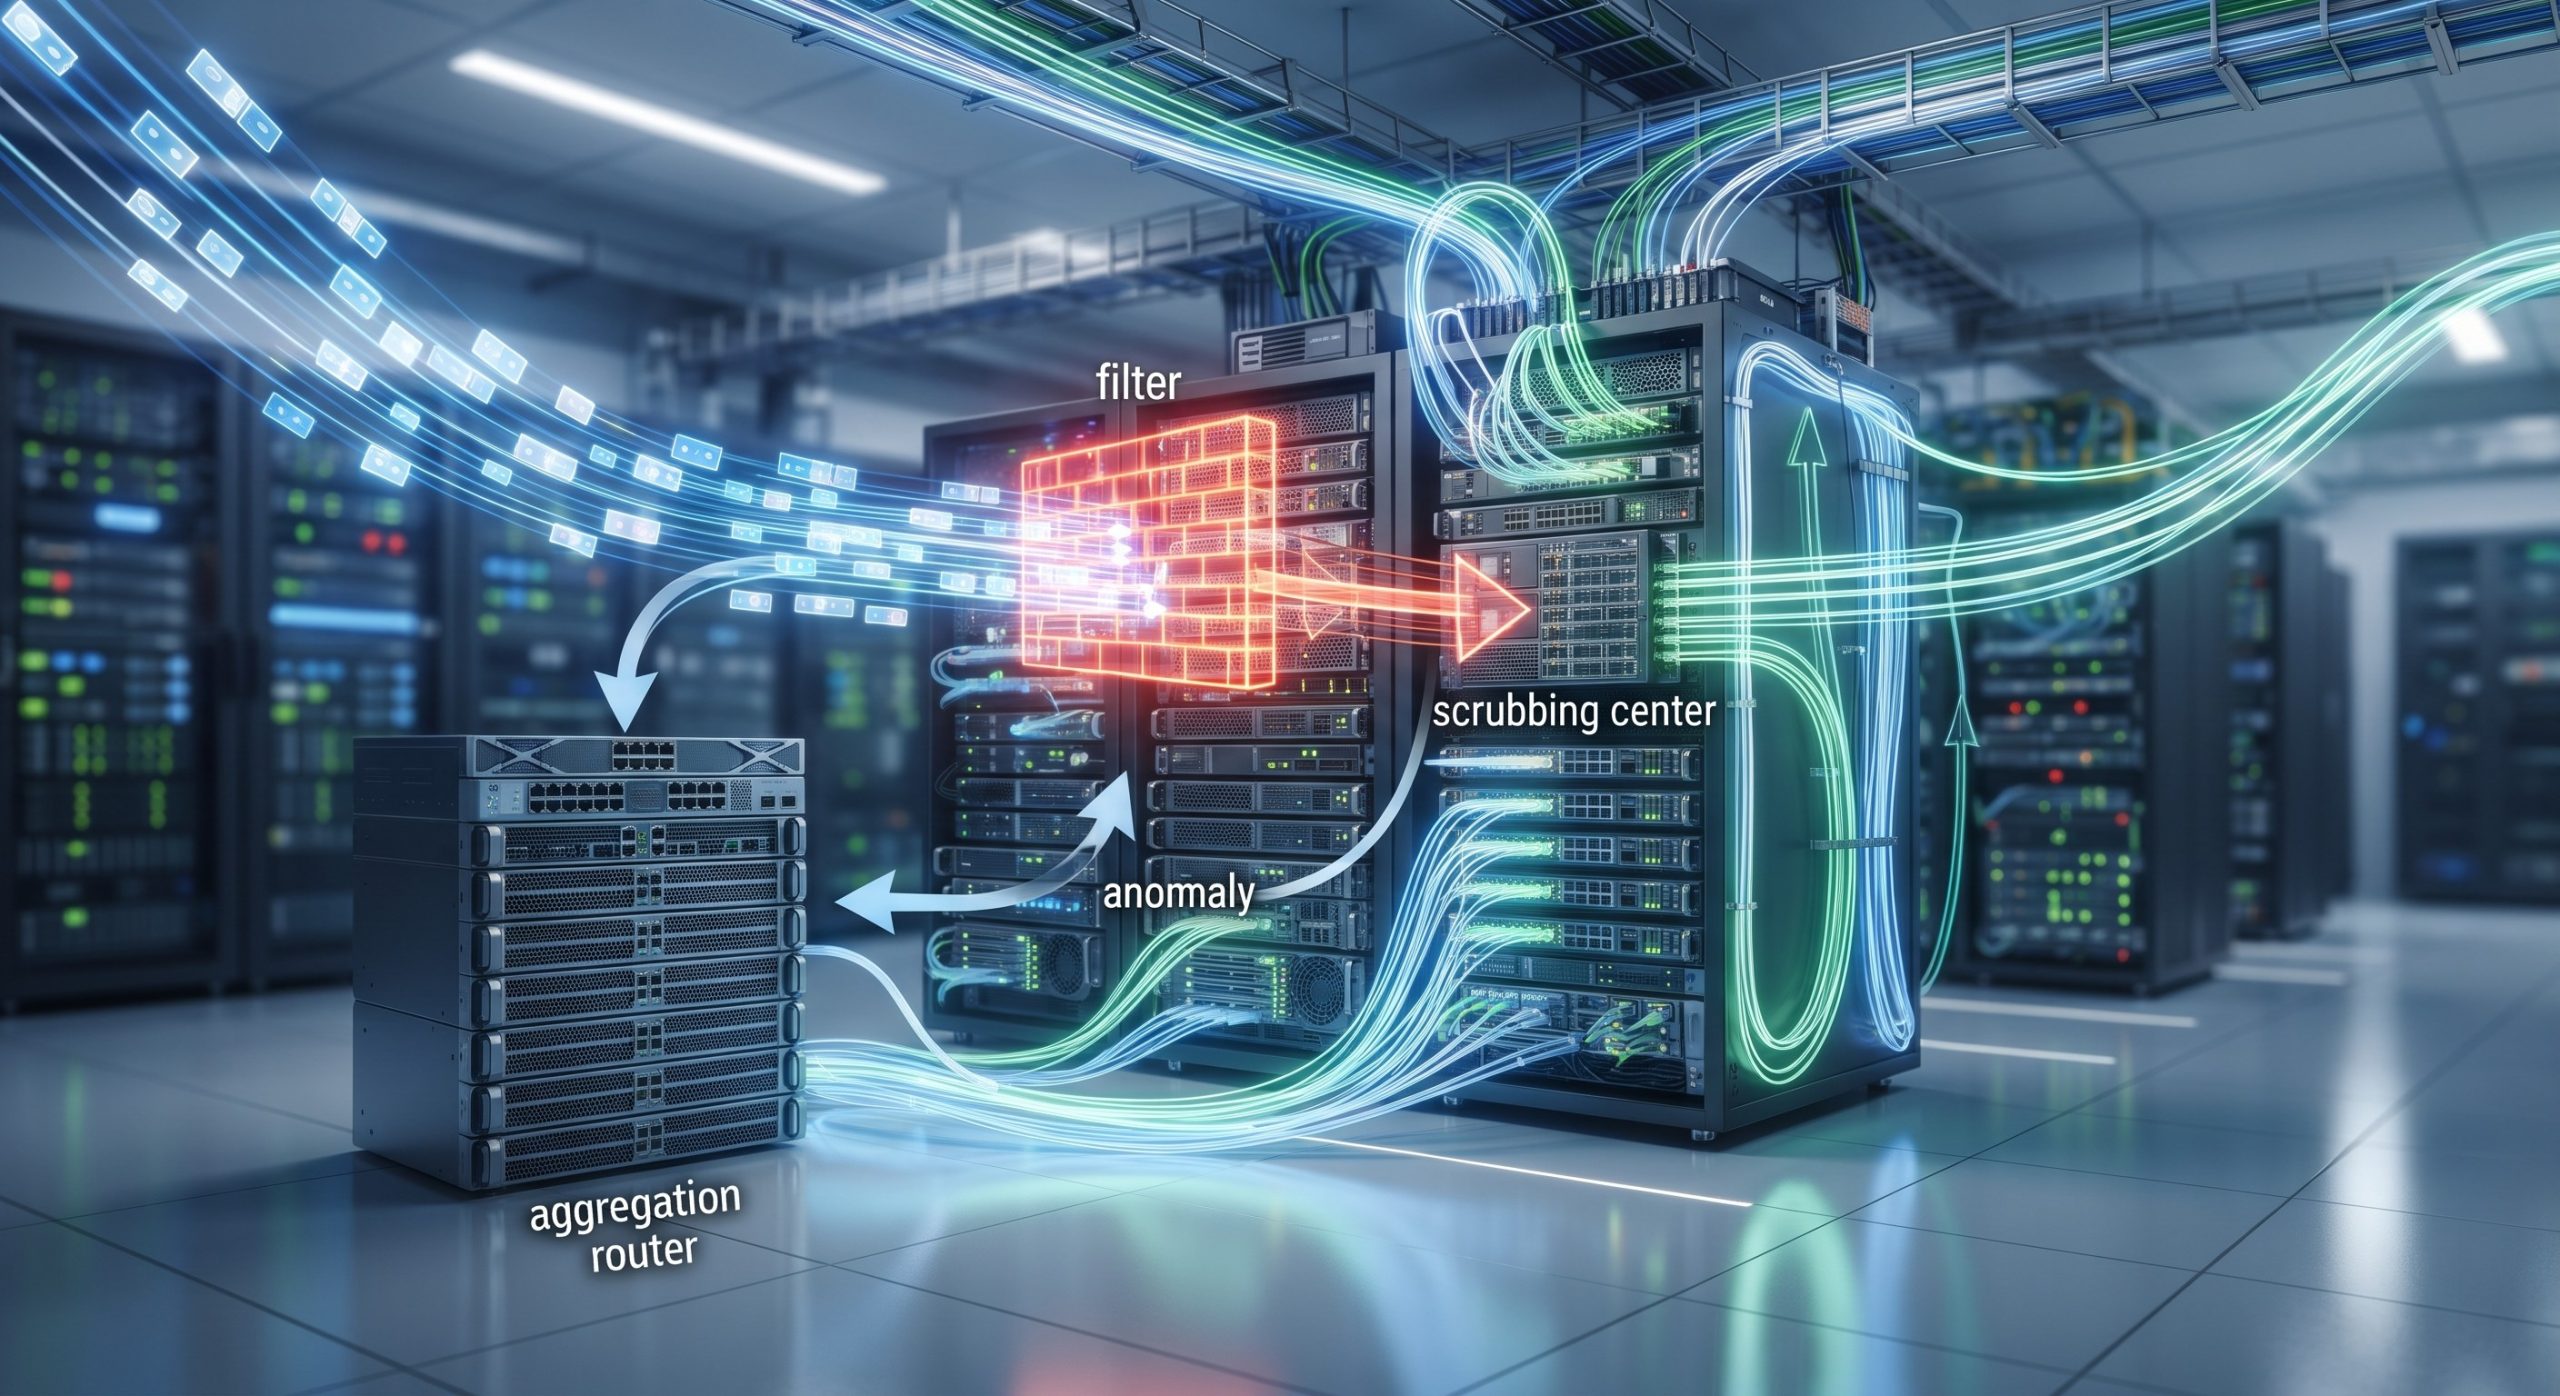
A production-grade BGP Flowspec architecture decouples the detection plane from the enforcement plane. The detection engine—often an sFlow/NetFlow collector or a dedicated DDoS mitigation appliance—must maintain a persistent iBGP session with the edge routers or a dedicated Flowspec Route Reflector. In a carrier-grade design, the Flowspec controller operates in an Active/Standby or Active/Active cluster with sub-second BGP Graceful Restart capabilities. If the primary controller fails, the standby must assume rule injection authority within the Hold Timer window (typically 90 seconds by default, but optimized to 9 seconds in high-availability designs) to prevent the withdrawal of active filters during an ongoing attack.
Hardware-based Route Reflectors (e.g., dedicated ASIC platforms) must support Flowspec NLRI reflection without punting to the CPU. The MTBF of the RR cluster is critical: a failure here severs the distribution of traffic-rate and traffic-action extended communities to all peering edges simultaneously. Modern implementations leverage BGP Add-Path and Flowspec validation procedures to ensure that only the originator (the controller) can inject rules for a given prefix, preventing rogue or stale rule propagation from compromising the forwarding integrity of the autonomous system.
ASIC-Level Enforcement and TCAM Exhaustion Thresholds
The reliability of automated scrubbing ultimately depends on the forwarding plane ASIC. When a Flowspec rule is received, the edge router compiles the match criteria (e.g., destination prefix, source port, protocol, packet length) into Ternary Content-Addressable Memory (TCAM) entries. Unlike software-based firewalls, hardware enforcement executes at line rate, but TCAM is a finite resource. Carrier-grade platforms (e.g., Juniper MX, Cisco ASR 9000, Nokia 7750 SR) typically support between 1,000 and 4,000 unique Flowspec filter entries per line card, depending on the ASIC generation and the complexity of the match fields.
Exceeding TCAM capacity during a complex attack can trigger a fail-open condition, where the router defaults to standard routing and allows the attack traffic to penetrate the core. Therefore, the Mean Time To Detect (MTTD) and Mean Time To Respond (MTTR) must be tightly coupled with TCAM monitoring. Automated controllers should implement rule aging and hysteresis to withdraw filters when attack traffic drops below a statistically significant threshold (e.g., 5% of peak), preventing stale entries from occupying precious hardware resources during peacetime operations.
| Key Parameter | Technical Specification |
|---|---|
| Protocol Standard | RFC 5575 (original), RFC 8955/8956 (updated validation & IPv6) |
| Match Fields (NLRI) | Destination/Source Prefix, IP Protocol, Port, ICMP Type/Code, TCP Flags, Packet Length, DSCP, Fragment |
| Action Communities | traffic-rate (0x8006), traffic-action (0x8007), redirect (0x8008), traffic-marking (0x8009) |
| TCAM Filter Capacity (Edge ASIC) | 1,000 – 4,000 unique Flowspec entries per line card (platform dependent) |
| BGP Convergence (Failover) | |
| Hardware MTBF (Chassis) | > 200,000 hours (Telcordia GR-63-CORE compliant platforms) |
| Typical Rule Injection Latency | 1 – 5 seconds (controller detection to edge enforcement) |
MTBF Metrics and Mission-Critical Deployment Scenarios
Quantifying Hardware Reliability in Scrubbing Pipelines
Evaluating the MTBF of a BGP Flowspec mitigation architecture requires a component-level analysis. The edge router chassis, typically rated for > 200,000 hours MTBF under Telcordia GR-63-CORE and RoHS compliance standards, is rarely the failure point. The critical reliability vectors are the fan trays, power supplies, and control-plane RE (Routing Engine) redundancy. In a dual-RE configuration, the standby RE must maintain a synchronized state of the Flowspec RIB (Routing Information Base) and FIB (Forwarding Information Base). Upon failover, the convergence time for Flowspec filters must not exceed 200 ms to prevent a micro-burst of attack traffic from overwhelming downstream stateful devices.
For Tier 1 ISPs and cloud scrubbing centers, the deployment topology often involves Flowspec Route Reflectors distributed across multiple Points of Presence (PoPs). The inter-PoP latency for rule propagation via BGP must be carefully budgeted. While a local iBGP session can distribute a rule in , cross-continental propagation over eBGP with route refresh can introduce 200–500 ms of latency. In a multi-terabit attack scenario, this delay is operationally acceptable only if the upstream transit providers support Flowspec and honor the traffic-rate community (0x8006) to rate-limit the attack closer to the source.
Case Study: Regional ISP Edge Scrubbing with 99.999% Availability
A European regional ISP serving 250,000 broadband subscribers recently transitioned from a centralized RTBH-only mitigation model to a distributed Flowspec architecture across 12 MX960 edge routers. The primary driver was the false-positive blackholing of legitimate VoIP and gaming traffic during UDP floods. By deploying ExaBGP-based controllers with anycast distribution, the ISP achieved a 94% reduction in collateral traffic loss during a 45 Gbps NTP amplification attack. The Flowspec rule—matching source-port 123 and packet-length > 468—was injected in 1.2 seconds and withdrawn 8 minutes later as the attack subsided. The edge routers maintained 99.999% availability, with zero control-plane resets attributable to Flowspec processing, validating the ASIC-based enforcement model over software-based ACLs.
Final Assessment
BGP Flowspec (RFC 5575) represents the current apex of automated edge traffic scrubbing when evaluated through the lens of carrier-grade reliability. The protocol’s separation of the match NLRI from the action extended community allows network architects to design surgical mitigation policies that preserve MTTR and MTBF targets even under multi-vector, high-volume attack conditions. However, the technology is not a turnkey panacea. The hardware ASIC TCAM limits, the BGP control-plane convergence during controller failover, and the cross-domain trust model for Flowspec validation remain critical engineering considerations. Organizations that invest in Flowspec-aware Route Reflectors, redundant controller clusters, and TCAM monitoring automation will realize a mitigation architecture that not only stops attacks but does so with the deterministic reliability expected of IEEE and ITU-T compliant carrier infrastructure. The operational verdict is clear: for edge scrubbing where uptime of legitimate services is non-negotiable, Flowspec is the most resilient tool available—provided the architect engineers the redundancy before the first attack packet arrives.

Leave a comment