Carrier-Grade Reliability: Evaluating MTBF and Redundancy in Model-Driven Telemetry with YANG Data Modeling for Core Networks
The modern core network operates under a paradox: it must deliver five-nines availability while the control plane increasingly relies on real-time, high-cardinality data streams that legacy monitoring architectures were never designed to sustain. Model-Driven Telemetry (MDT) with YANG data modeling has emerged as the architectural answer to this tension, replacing the inefficient pull-based SNMP paradigm with a push-based, structured streaming model that aligns device instrumentation directly with operational intent . However, the transition from periodic polling to continuous telemetry introduces new reliability vectors that network architects must rigorously evaluate. This analysis examines the carrier-grade characteristics of MDT deployments, focusing on the Mean Time Between Failures (MTBF) implications of telemetry pipelines, the redundancy mechanisms required to maintain SLA compliance, and the architectural trade-offs that determine whether a telemetry deployment enhances or degrades core network resilience.
Dual-Engine Failover Architecture for Telemetry Collection
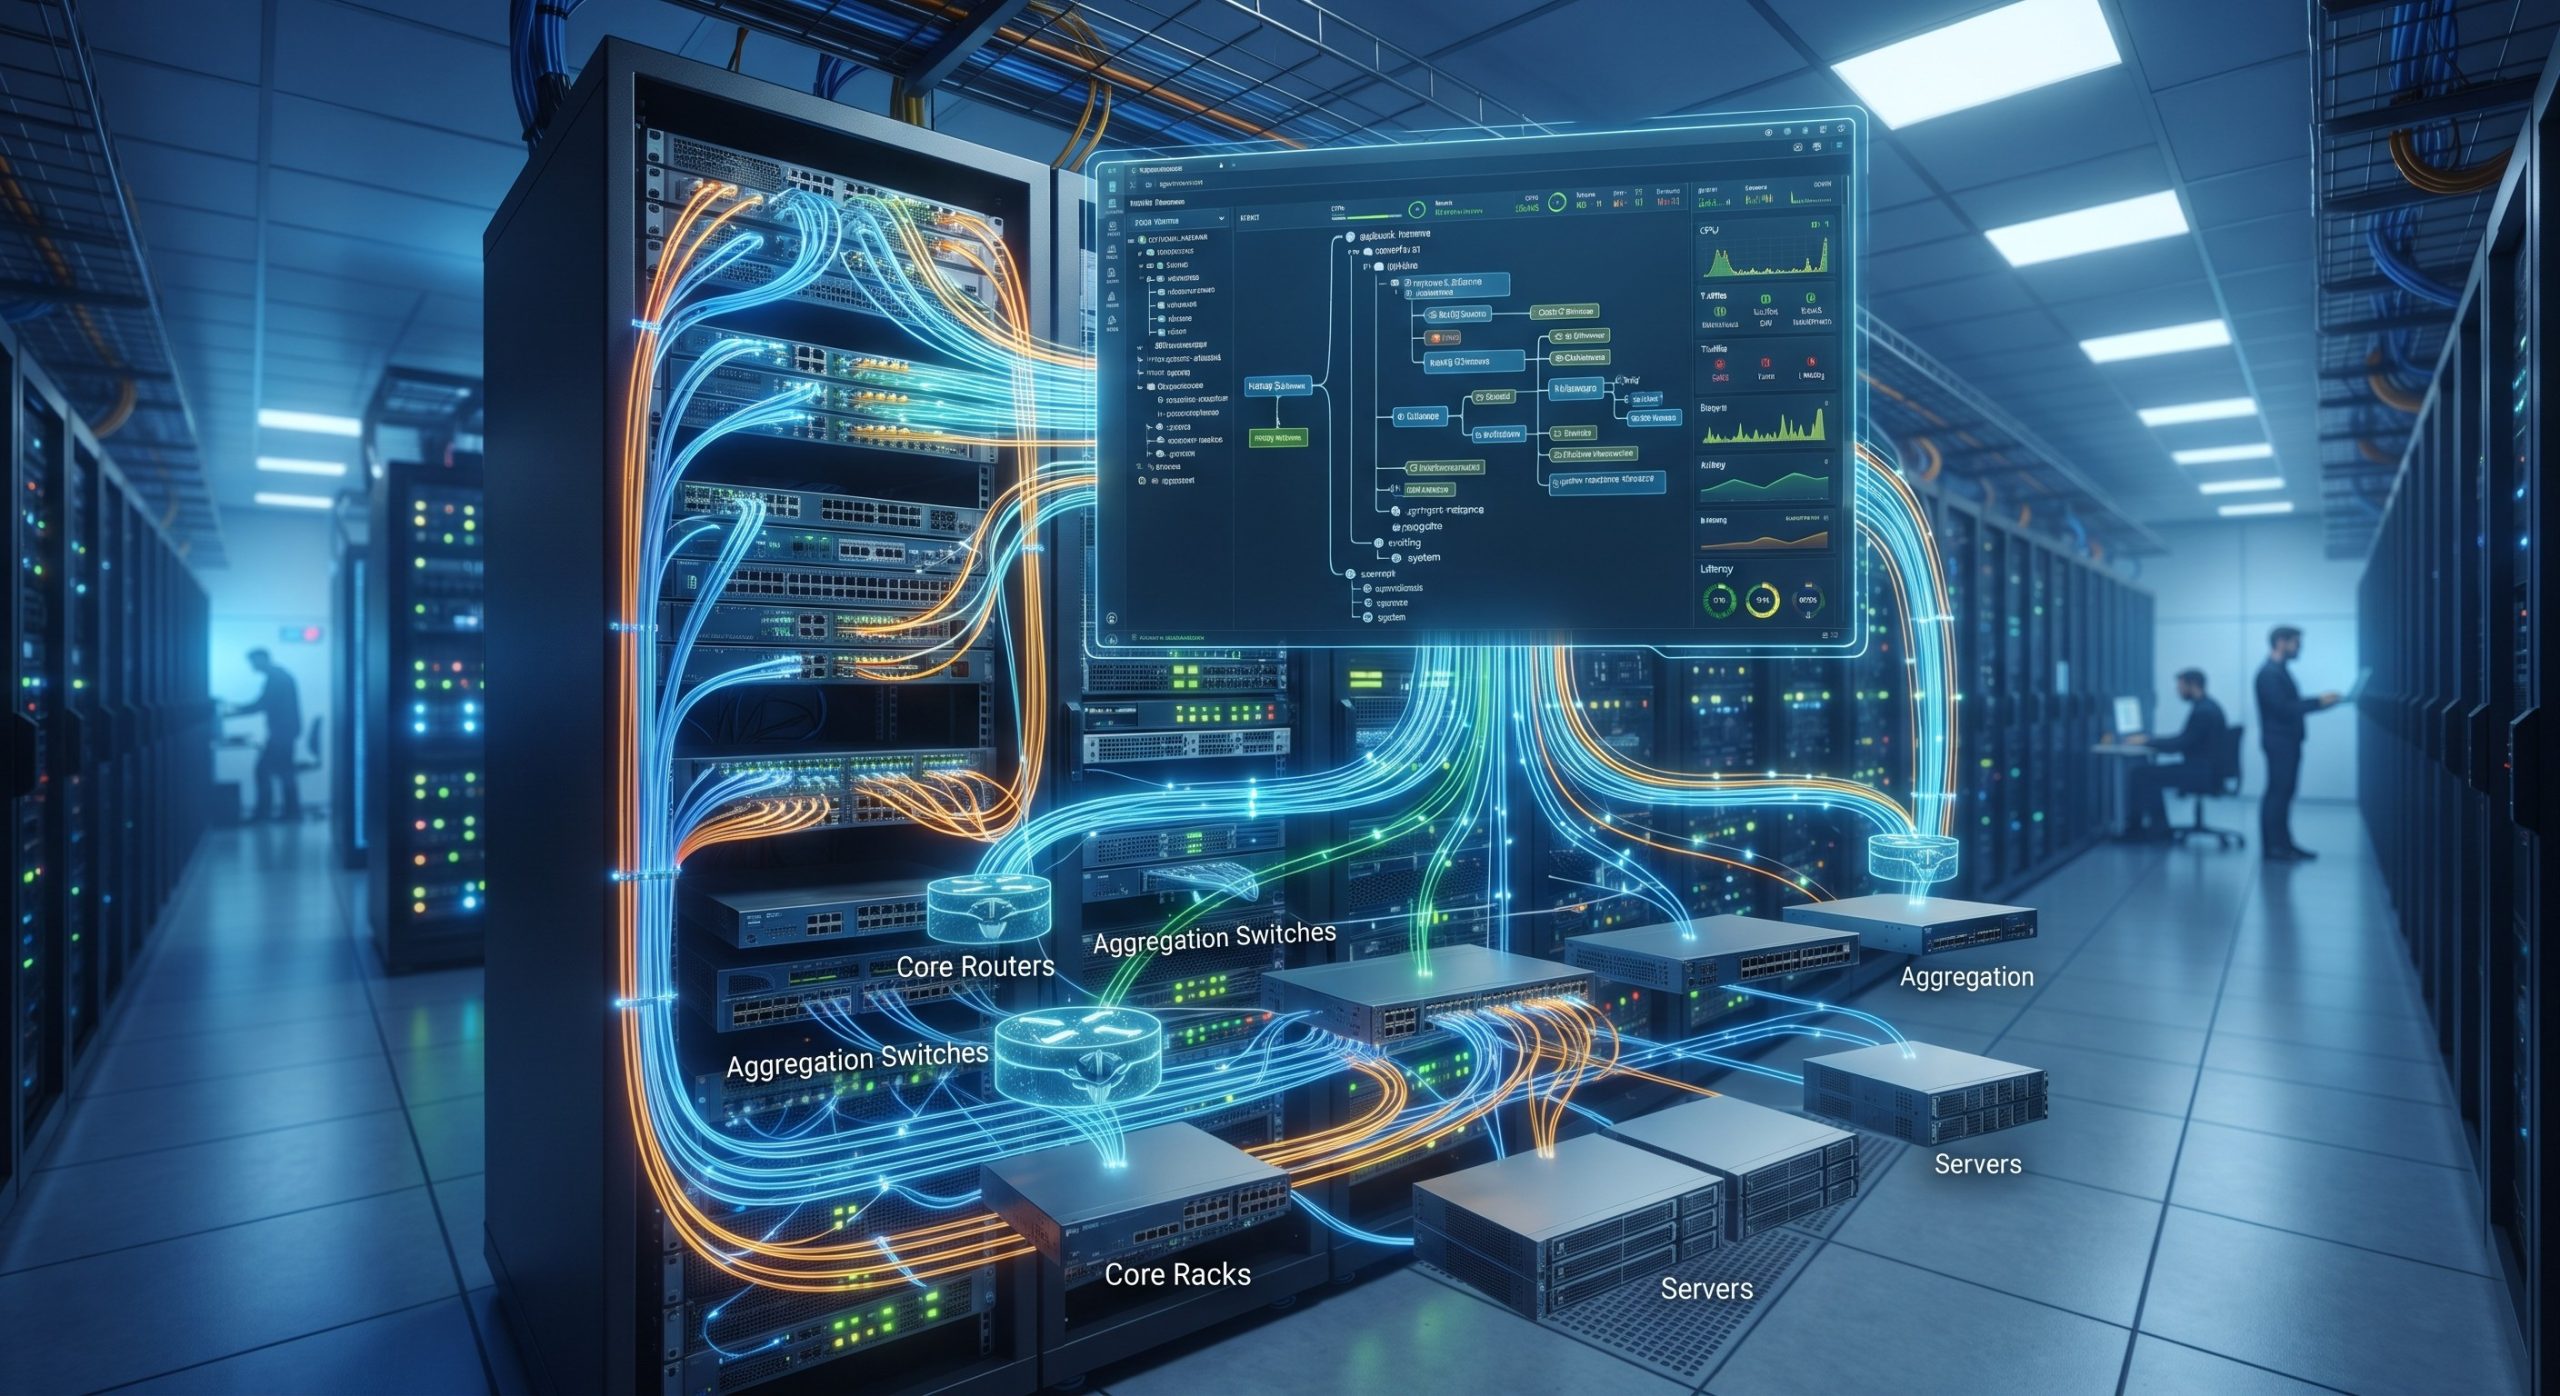
The reliability of a telemetry-driven core network is not solely a function of router hardware MTBF; it is equally dependent on the resilience of the telemetry collection and transport layer. A single gRPC or NETCONF collector session, no matter how well-provisioned, represents a single point of failure for visibility into the forwarding plane. Carrier-grade MDT deployments therefore mandate a dual-engine failover architecture that mirrors the redundancy expectations of the routing control plane itself.
Active-Active Collector Redundancy
In an active-active configuration, core routers establish simultaneous telemetry sessions with two or more independent collectors. The YANG Push subscription model, as defined in IETF specifications, supports multiple receivers for the same data stream, allowing each collector to maintain an independent subscription lifecycle . When a primary collector experiences a failure—whether due to software crash, network partition, or maintenance—the router continues streaming to the secondary collector without interruption. This eliminates the telemetry gap that would otherwise occur during collector failover, a critical requirement for SLA monitoring where even a 30-second visibility loss can trigger compliance violations.
Router-Side Subscription Persistence
The reliability of the telemetry pipeline also depends on the router’s ability to maintain subscription state across control plane restarts. Carrier-grade implementations persist YANG-modeled subscription configurations in non-volatile storage, ensuring that a route processor failover or a soft reload does not silently terminate active telemetry streams. Field data from Cisco IOS XR deployments indicates that subscription persistence reduces recovery time from minutes to sub-second intervals, preserving telemetry continuity through planned maintenance events .
MTBF Metrics and Telemetry Pipeline Availability
Quantifying the reliability of an MDT deployment requires extending traditional hardware MTBF analysis to encompass the telemetry software stack. A core router may achieve an MTBF exceeding 300,000 hours for its forwarding ASIC and power subsystems, yet the telemetry agent—responsible for encoding YANG-modeled data into Protocol Buffers or JSON and transmitting it over gRPC—represents a separate failure domain with its own availability characteristics.
Operational data from carrier deployments suggests that the dominant telemetry pipeline failure modes are not hardware-related but stem from subscription misconfiguration, collector resource exhaustion, and TLS certificate expiry. Each of these failure modes is addressable through architectural discipline: configuration validation via YANG models prevents incompatible subscription paths from being committed; collector sizing calculations based on expected streaming throughput (measured in thousands of updates per second per device) prevent buffer overflows; and automated certificate rotation eliminates the silent expiry failures that can disconnect telemetry streams without triggering traditional link-down alarms.
| Reliability Parameter | Carrier-Grade Specification |
|---|---|
| Telemetry Pipeline Availability Target | ≥ 99.999% (five-nines) for critical interface counters |
| Collector Failover Time (Active-Active) | |
| Maximum Acceptable Telemetry Gap (SLA-Critical Paths) | ≤ 60 seconds before NOC alert escalation |
| YANG Push Subscription Persistence | Survives route processor failover and soft reload |
| Transport Security | gRPC with TLS 1.3; automated certificate rotation |
| On-Change Subscription Volume Reduction | 70–85% compared to periodic sampling of all paths |
Mission-Critical Deployments: Telemetry Reliability in Practice
The reliability claims of MDT architectures are validated through deployment scenarios where telemetry continuity directly correlates with service assurance. Consider a Tier-1 ISP core network spanning 48 core routers across four metro regions, each router streaming interface statistics, queue depths, and hardware environmental data at 10-second intervals via gRPC to a redundant collector pair. The operational requirement is unambiguous: any gap exceeding 60 seconds in telemetry data for a given interface must trigger an alert to the NOC, as this corresponds to the window during which an SLA-impacting degradation could occur undetected.
In this deployment, the failure mode analysis reveals that collector-side storage saturation is the most probable telemetry pipeline disruption, not router-side agent failure. The YANG Push on-change subscription mechanism mitigates this risk by transmitting data only when values cross defined thresholds, reducing steady-state telemetry volume by an estimated 70–85% compared to periodic sampling of all subscribed paths . This architectural choice directly improves pipeline MTBF by reducing the I/O pressure on collector storage subsystems, extending the time-to-exhaustion under peak load conditions.
For core networks supporting financial transaction traffic or real-time media delivery, where packet loss exceeding 0.001% constitutes a reportable SLA breach, the reliability calculus shifts further. These environments demand telemetry latency below 1 second for critical counters, necessitating high-frequency streaming that places correspondingly higher demands on the redundancy architecture. The dual-engine failover model described earlier becomes non-negotiable, and collector failover must be validated through quarterly chaos engineering exercises that simulate abrupt primary collector termination under full production telemetry load.
Final Assessment: Reliability as an Architectural Discipline
The carrier-grade reliability of Model-Driven Telemetry with YANG Data Modeling is not an inherent property of the protocol stack; it is an outcome of deliberate architectural choices that treat the telemetry pipeline with the same redundancy rigor applied to the routing control plane. The YANG data modeling framework provides the semantic foundation—a shared, vendor-neutral contract between device and collector that eliminates the ambiguity inherent in SNMP MIB interpretation . The streaming push model provides the efficiency gain—near-real-time visibility without the CPU and bandwidth penalties of polling . But it is the redundancy architecture—active-active collectors, subscription persistence, and disciplined certificate and configuration management—that determines whether the telemetry system achieves the 99.999% availability that core network SLAs demand.
Network architects evaluating MDT for core deployments should treat telemetry reliability metrics as first-class design constraints, not afterthoughts. The MTBF of the router hardware is necessary but insufficient; the MTBF of the complete telemetry pipeline—from YANG subscription establishment through gRPC transport to collector persistence—is the metric that ultimately determines whether the network operations team can trust the data stream when it matters most: during the incidents that telemetry exists to detect.
Leave a comment