The SLA Paradox: When 800G Speed Meets AI Training Economics
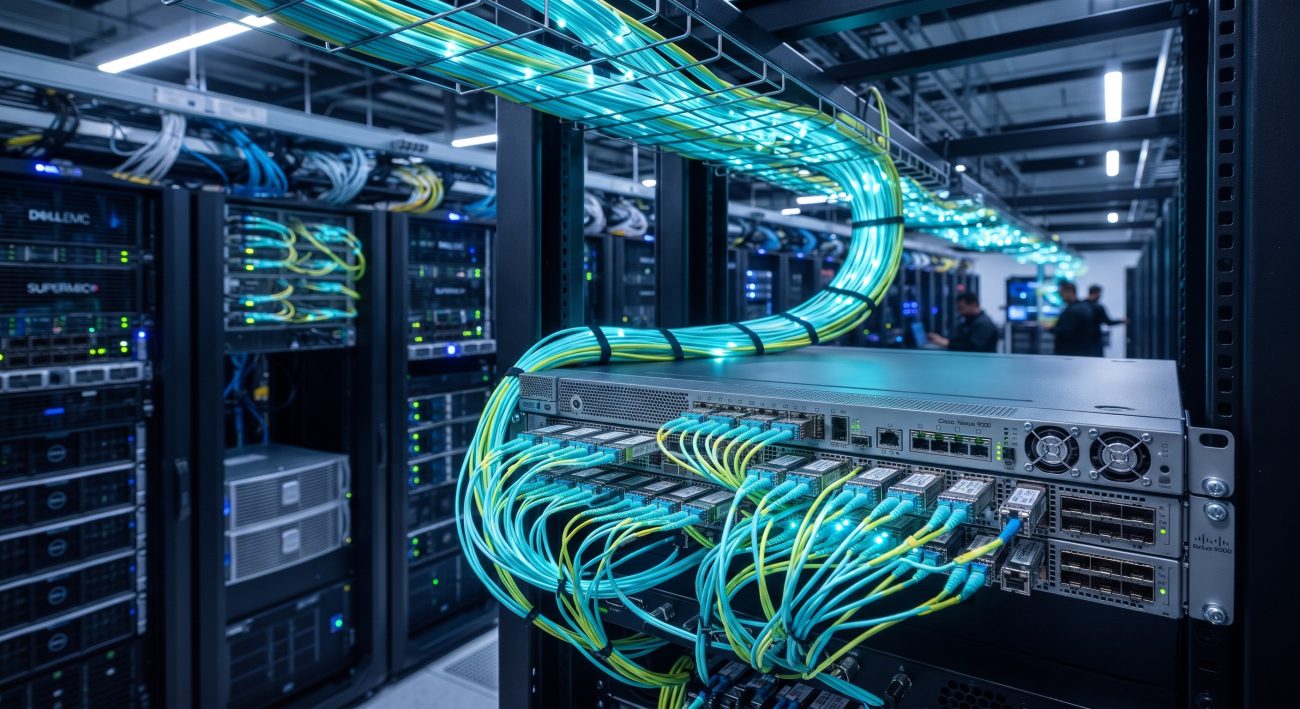
The deployment of 800G high-speed optical transceivers in Spine-Leaf AI clusters is not merely a bandwidth upgrade; it is a fundamental shift in failure economics. In a conventional cloud data center, a single transceiver failure triggers a route convergence event measured in seconds. In a GPU-synchronized AI training cluster, a single link flap on a spine-leaf interconnect can stall tens of thousands of compute accelerators, resulting in idle GPU hours that directly translate to tens of thousands of dollars in lost research velocity per incident .
Network architects specifying 800G optics for AI fabric deployments must therefore prioritize MTBF (Mean Time Between Failures) and redundancy architecture with the same rigor applied to switch ASIC selection. This analysis evaluates the carrier-grade reliability parameters of 800G transceivers within the Spine-Leaf topology, referencing IEEE 802.3 and ITU-T G.709.5 compliance frameworks, and provides a quantified assessment of failover behavior, thermal derating risks, and operational availability.
Dual-Engine Failover Architecture: Redundancy at the Physical and Logical Layers
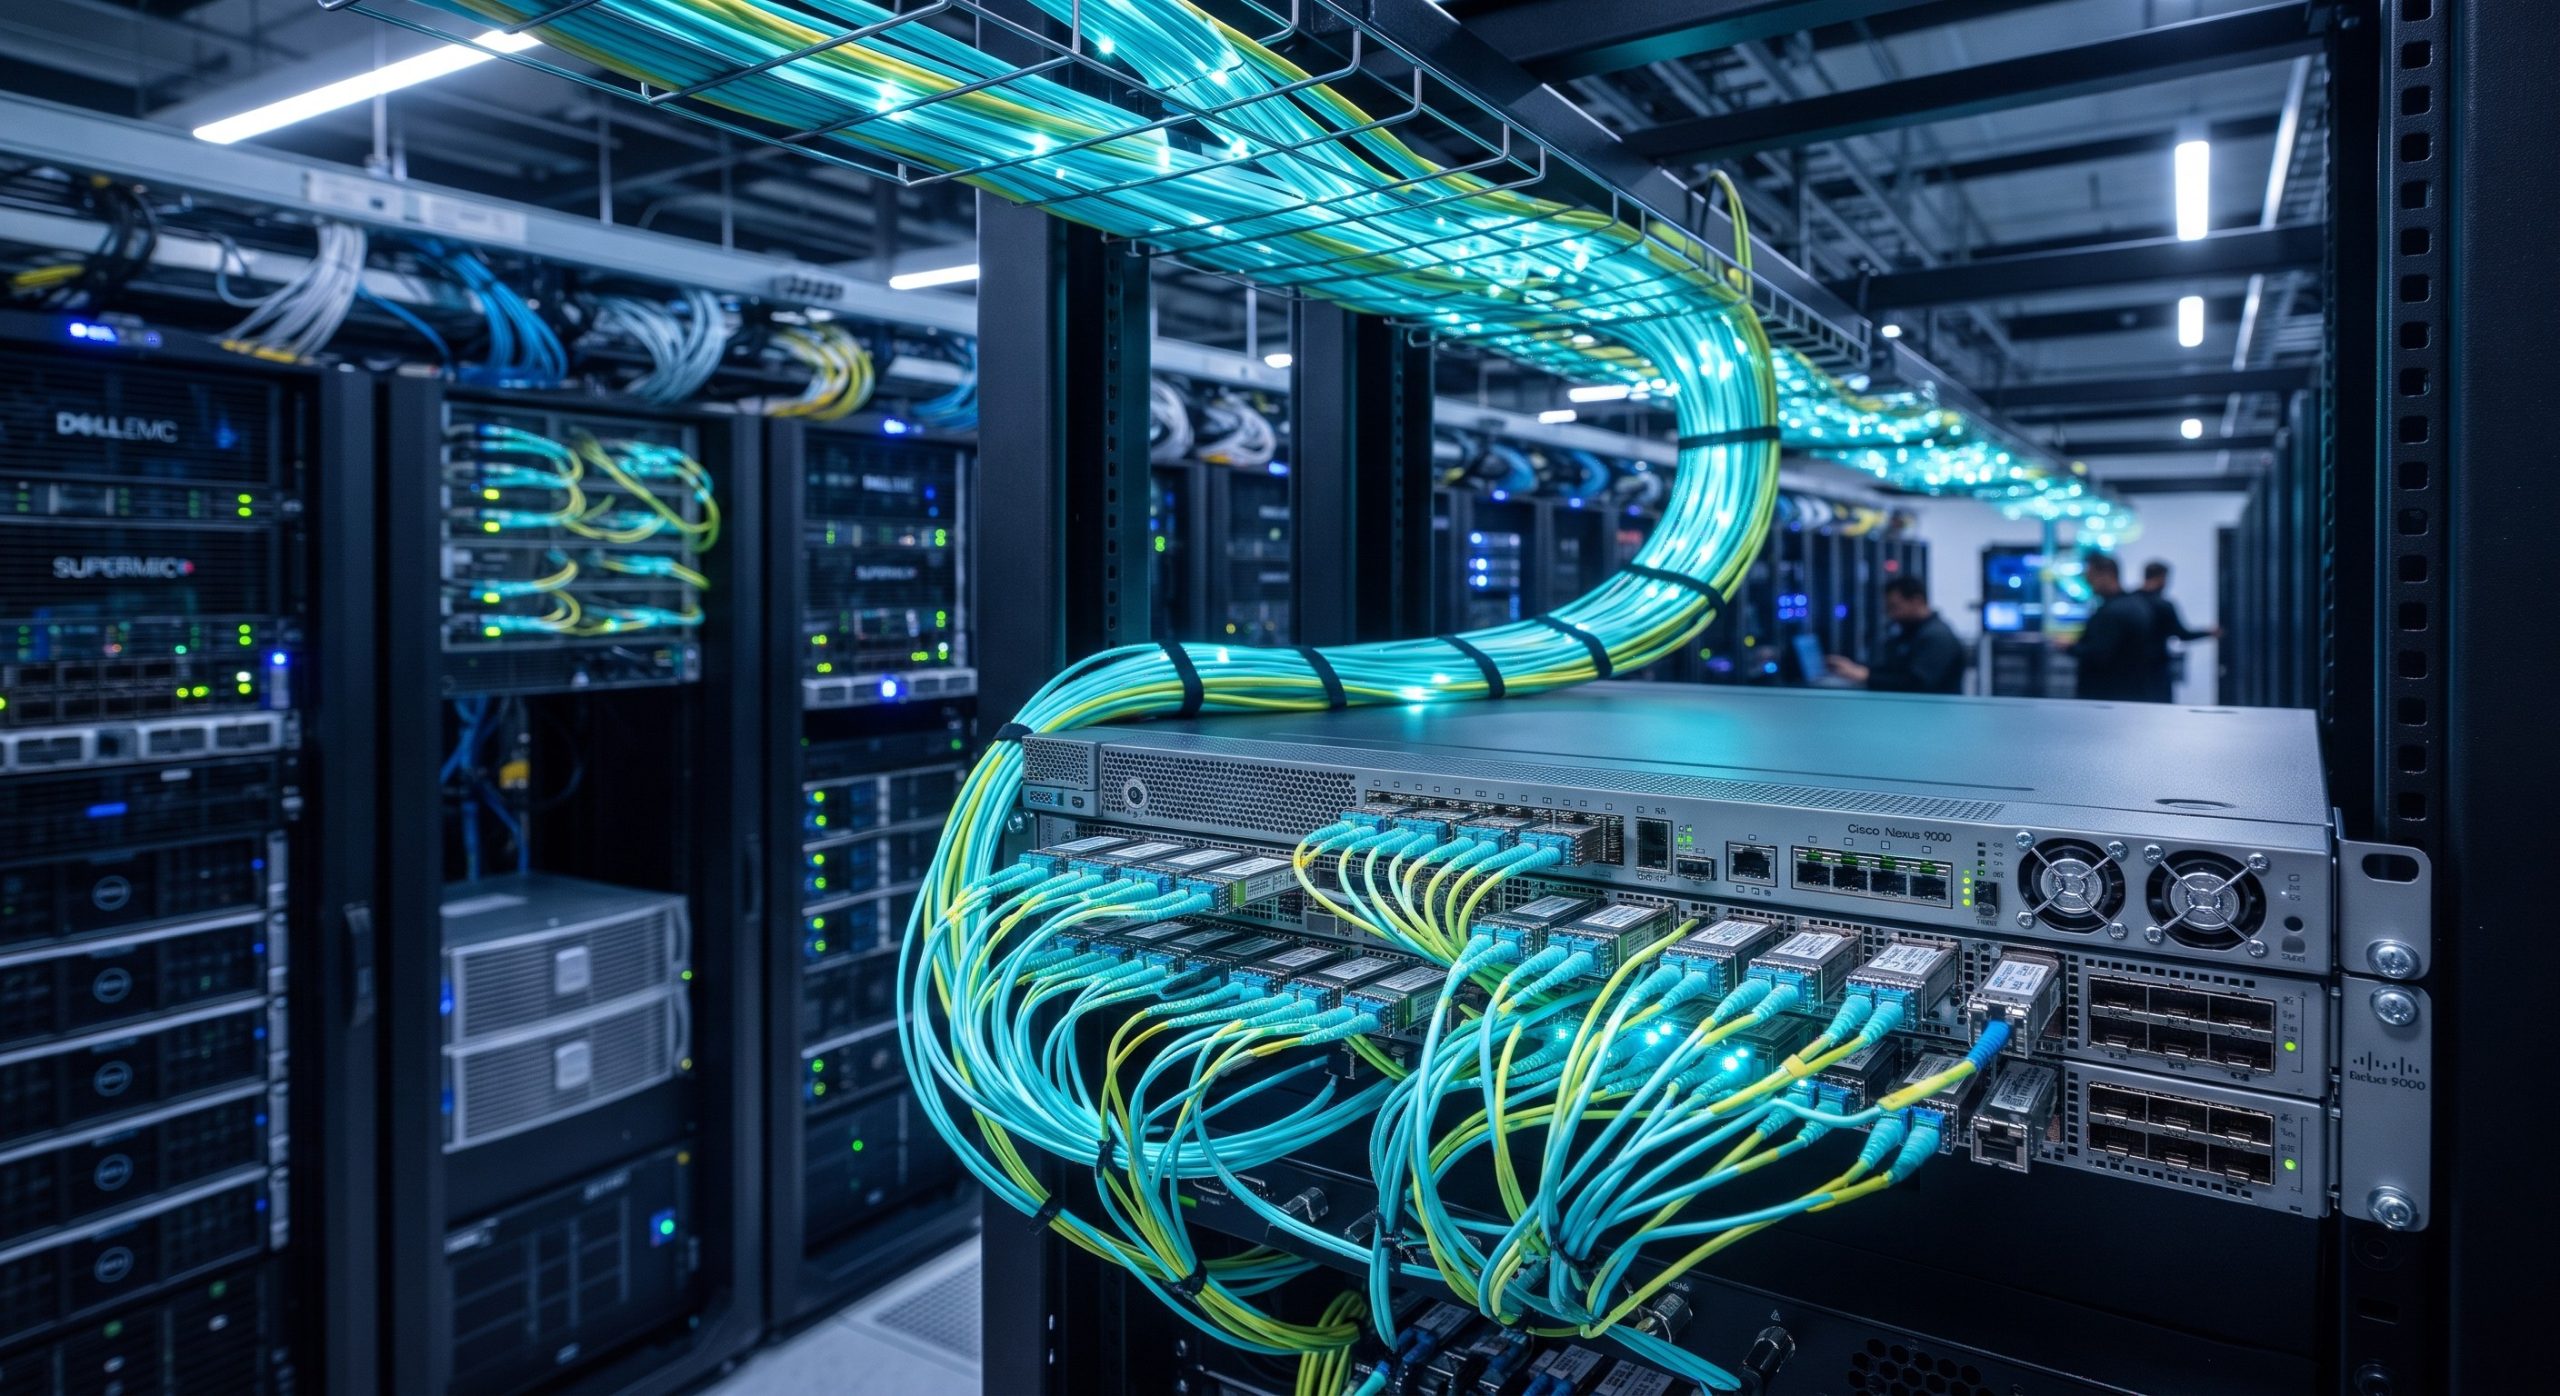
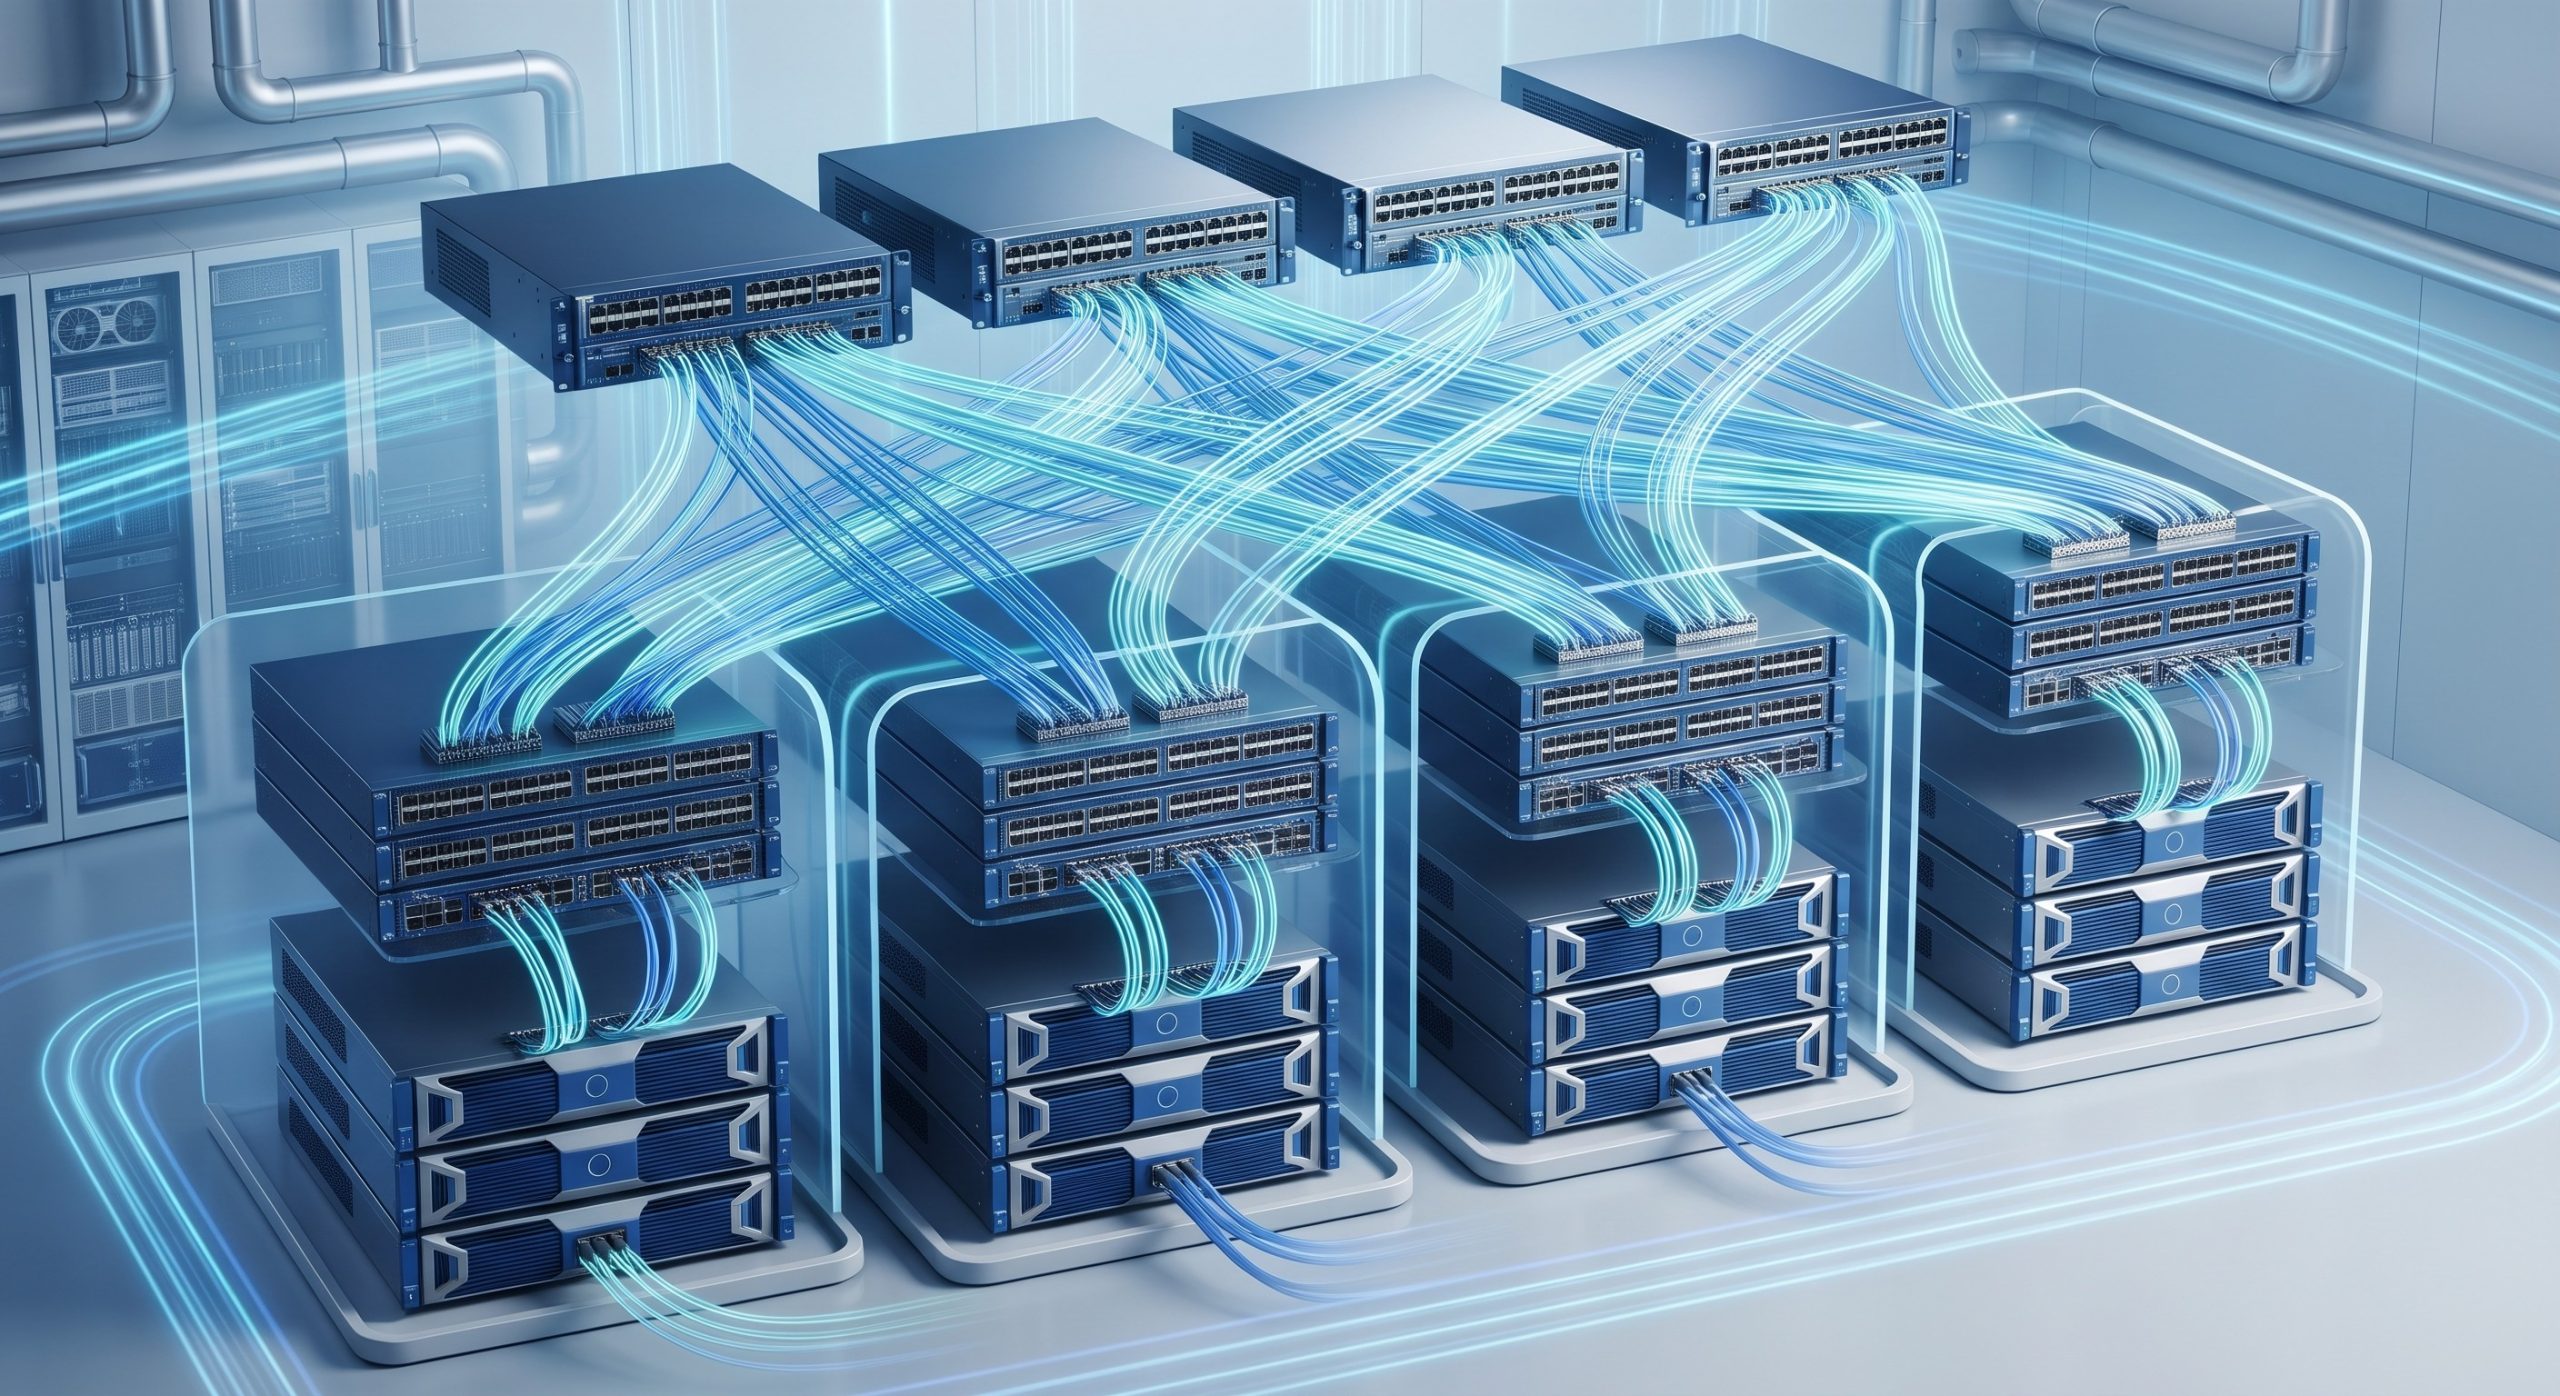
The Spine-Leaf architecture for AI clusters relies on ECMP (Equal-Cost Multi-Path) routing to distribute training traffic across multiple spine switches. However, the physical layer redundancy model for 800G optics introduces failure modes absent in lower-speed fabrics. A conventional 400G transceiver typically houses a single DSP and a single optical engine. A 800G OSFP module, by contrast, may encapsulate two independent 400G optical engines within a shared mechanical housing to feed two distinct host ASIC lanes .
Asymmetric Failure Domain in Twin-Port 800G Modules
This twin-port architecture creates a subtle reliability consideration: a thermal event or laser degradation affecting one internal 400G lane may degrade the entire module’s DOM (Digital Optical Monitoring) telemetry, potentially triggering the host to disable both logical links. For carrier-grade deployments, architects must verify that the switch ASIC firmware supports per-lane fault isolation rather than module-level shutdown. Without this capability, the theoretical redundancy of dual-spine connectivity is compromised by a single physical module failure domain.
Forward Error Correction and Link Stability Margins
At 800G, the RS-FEC (Reed-Solomon Forward Error Correction) budget consumes a significant portion of the link margin. A transceiver that passes initial link training may exhibit elevated pre-FEC BER under sustained thermal load, leading to intermittent link flaps that are far more damaging to AI training throughput than a hard failure. Field data from 800G rollouts indicates that a substantial portion of early-life instability correlates with FEC profile mismatch and thermal derating rather than outright optic failure . Specification teams should mandate DOM validation gates that verify pre-FEC BER stability across a controlled thermal cycle before production cutover.
MTBF Metrics and the Real Cost of Transceiver Downtime
The industry-standard annualized failure rate for data center optical transceivers typically ranges from 0.3% to 0.5% . In a cluster with 10,000 GPUs interconnected via a spine-leaf fabric, the transceiver population can exceed 25,000 to 40,000 modules. At a 0.4% AFR, this translates to a theoretical average of one transceiver failure every three to four days . For an AI training workload that cannot tolerate checkpoint rollback without cost, this failure frequency represents a persistent operational tax.
Vendors differentiating on reliability report failure rates in the 0.1% range, a 50%+ improvement over the industry baseline . While a single 800G module’s unit cost may be measured in the hundreds to low thousands of dollars, the cost of unplanned downtime in a large-scale training cluster dwarfs the hardware replacement expense. Operational models should incorporate a spares ratio and a hot-spare port strategy that accounts for the MTBF delta between vendor tiers, not merely the per-unit acquisition price.
| Reliability Parameter | Carrier-Grade Specification | Operational Relevance |
|---|---|---|
| Annualized Failure Rate (AFR) | Target ≤ 0.1% (Premium Tier) vs. Industry Baseline 0.3–0.5% | Determines expected failure events per 10,000-module cluster |
| Max Power Dissipation (DSP-based 800G) | 16.0 W to 16.5 W (typical OSFP DR8/SR8) | Drives thermal derating and front-panel density limits |
| FEC Compliance | IEEE 802.3 RS-FEC (544/514) / ITU-T G.709.5 FlexO | Pre-FEC BER margin critical for link stability |
| Operating Case Temperature | 0°C to 70°C (Commercial) / -5°C to 70°C (Extended) | Must be validated under sustained AI workload thermal profiles |
| Management Interface | CMIS Rev 5.0+ with per-lane DOM visibility | Enables fault isolation and predictive maintenance |
| Form Factor / Redundancy | OSFP Twin-Port (2×400G internal engines) | Requires switch firmware support for per-lane failover |
Mission-Critical Deployment Scenarios: Redundancy in Practice
Scenario A: Leaf-Spine Uplink Redundancy with 800G Twin-Port Modules
In a typical AI cluster reference design, each leaf switch connects to multiple spine switches using 800G links. When twin-port OSFP modules are deployed, the two internal 400G engines may be routed to different spine switches to provide physical path diversity. This configuration tests the switch’s ability to maintain forwarding state when one internal lane fails. BGP graceful restart and BFD (Bidirectional Forwarding Detection) with sub-second timers are essential to ensure that the surviving lane absorbs traffic without triggering a full topology reconvergence event.
Scenario B: Thermal Margins Under Sustained AI Workloads
AI training traffic differs from general data center traffic in its sustained line-rate burst characteristics. A transceiver that operates within thermal limits under bursty web traffic may exceed its case temperature threshold during hours-long gradient synchronization phases. The power dissipation of mainstream DSP-based 800G modules can reach 16W to 16.5W , creating localized hot spots in high-density leaf switch line cards. Deployment planning must account for front-panel airflow impedance and the thermal derating curve of the specific module SKU, particularly when mixing finned-top (switch-side) and flat-top (NIC-side) variants in adjacent rack configurations .
Scenario C: ITU-T G.709.5 FlexO Compliance for Short-Reach Interconnects
ITU-T G.709.5 specifies FlexO short-reach interfaces at 100G, 200G, 400G, and 800G, providing a standardized forward error correction structure suitable for intra-data center applications . While most AI cluster deployments rely on IEEE 802.3 Ethernet framing, operators with multi-vendor transport requirements or emerging 800G ZR/ZR+ coherent interfaces should verify that transceiver management interfaces support the CMIS (Common Management Interface Specification) registers required for FlexO negotiation. This is particularly relevant for DCI (Data Center Interconnect) links that bridge AI training clusters across buildings or campuses, where ITU-T compliance ensures interoperability across transport equipment vendors.
Final Assessment: Reliability as a Procurement Criterion
The 800G transceiver selection process for spine-leaf AI clusters must elevate MTBF and failover transparency from secondary considerations to primary procurement gates. The architectural elegance of a non-blocking spine-leaf fabric is neutralized if the physical layer introduces opaque failure domains or thermal-induced instability under sustained training loads.
Three actionable criteria emerge for carrier-grade evaluation: First, mandate per-lane fault isolation validation with the specific switch ASIC firmware version in use, not merely datasheet compliance. Second, require pre-FEC BER stability data across the full operating temperature range, with DOM alarm thresholds correlated to the FEC budget rather than generic optical power windows. Third, quantify total cost of ownership inclusive of spares inventory and expected downtime events, recognizing that a 0.1% failure rate module and a 0.5% failure rate module are not interchangeable inputs in an AI training cluster where every link flap has a measurable GPU-cost.
The industry’s shift toward LPO (Linear Pluggable Optics) and lower-power 800G variants promises to reduce thermal density and potentially improve MTBF by removing DSP-related failure modes . Until those architectures achieve the operational maturity of DSP-based modules, reliability engineering for 800G AI fabrics must remain anchored in empirical thermal validation, rigorous FEC alignment, and a redundancy model that accounts for the twin-port physical reality of modern 800G hardware.
Leave a comment