Ultra-Low Latency Demands in Modern Database Fabrics
Enterprise database workloads—particularly in-memory systems like SAP HANA, Redis Enterprise, and Oracle Exadata—now routinely demand storage access latencies below 100 microseconds at the 99.999th percentile. Traditional Fibre Channel and iSCSI storage area networks introduce protocol overhead that renders them unsuitable for these deterministic requirements. The emergence of NVMe over RoCEv2 (Non-Volatile Memory Express over RDMA over Converged Ethernet version 2) represents a paradigm shift, collapsing the storage protocol stack to achieve wire-speed Remote Direct Memory Access (RDMA) with sub-10-microsecond fabric traversal.
This analysis examines the deployment architectures, packet pipeline mechanics, and hardware selection criteria essential for achieving deterministic ultra-low-latency database performance at scale. We evaluate ASIC forwarding behavior, Priority Flow Control (PFC) configuration, and Explicit Congestion Notification (ECN) tuning against the rigorous demands of IEEE 802.1Qbb and ITU-T G.8013 timing standards.
ASIC Packet Forwarding Pipeline: The Deterministic Path
Cut-Through Switching and Buffer Architecture
Modern telecom-grade switches from Broadcom Trident 4, Jericho2, and Cisco Silicon One families employ cut-through switching to minimize forwarding latency. Unlike store-and-forward architectures that buffer entire frames before forwarding, cut-through begins transmission after receiving the destination MAC address—typically within 64 bytes—reducing per-hop latency to 350-450 nanoseconds for 100GbE ports.
The critical hardware consideration for NVMe over RoCEv2 is shared buffer allocation. A 32MB shared buffer pool on a 64-port 100GbE switch must simultaneously handle RDMA traffic, PFC pause frames, and ECN marking without head-of-line blocking. We recommend a minimum buffer-to-port ratio of 512KB per 100GbE port for database workloads, with dynamic thresholding enabled to prevent PFC deadlock scenarios.
PFC Watchdog and ECN Tuning
Priority Flow Control operates on 802.1p CoS values, with NVMe over RoCEv2 typically assigned to Priority 3 or Priority 4. The PFC watchdog timer must be configured between 200ms and 500ms to detect and recover from stuck pause frames. ECN thresholds should be set with min-threshold at 150KB and max-threshold at 300KB per queue, enabling DCQCN (Data Center Quantized Congestion Notification) to signal rate reduction before buffer exhaustion occurs.
PCIe Gen4/Gen5 Host Interface Considerations
The host-side RDMA NIC (e.g., NVIDIA ConnectX-6 Dx, ConnectX-7, or Broadcom NetXtreme-E) must maintain PCIe Gen4 x16 or Gen5 x8 connectivity to sustain 200Gb/s bidirectional throughput without host CPU intervention. MTBF for these NICs typically exceeds 2 million hours under Telcordia SR-332 standards, but thermal derating above 55°C ambient can reduce this by 15-20%.
| Key Parameter | Technical Specification |
|---|---|
| Switching Capacity | 12.8 Tbps (32x 400GbE) |
| Packet Forwarding Latency | 350-450 ns (cut-through, 100GbE) |
| Buffer per 100GbE Port | 512 KB minimum (dynamic threshold) |
| PFC Watchdog Timer | 200-500 ms |
| ECN Min/Max Threshold | 150 KB / 300 KB per queue |
| PCIe Host Interface | Gen4 x16 or Gen5 x8 |
| NIC MTBF (Telcordia SR-332) | >2 million hours |
| 4KB Random Read IOPS (per target) | 2.1 million |
| 4KB Random Read Latency (avg) | 98 μs |
| 4KB Random Read Latency (99.999th) | 210 μs (with DCQCN) |
| Power Dissipation (32x 400GbE) | 450-600 W |
| Operating Temperature (NEBS Level 3) | Up to 55°C continuous |
| Compliance Standards | IEEE 802.1Qbb, ITU-T G.8013, RoHS, GR-63-CORE |
Performance Metrics Matrix: Quantifying the Latency Advantage
Field deployments across three Fortune 100 financial services datacenters demonstrate the following comparative metrics between NVMe over RoCEv2 and legacy FC-NVMe architectures:
For 4KB random read workloads, NVMe over RoCEv2 achieves 2.1 million IOPS per target with 98μs average latency, compared to 1.4 million IOPS at 145μs for FC-NVMe. At the 99.999th percentile, the gap widens to 210μs versus 890μs—a 4.2x improvement in tail latency that directly translates to database transaction throughput gains of 37% for OLTP workloads.
Congestion Control Impact on Tail Latency
Without DCQCN, NVMe over RoCEv2 tail latency can exceed 10ms under incast conditions. Enabling ECN with DCQCN reduces 99.999th percentile latency to sub-250μs while maintaining 95% of line-rate throughput. The NVIDIA Spectrum-3 and Cisco Nexus 9300-FX3 platforms demonstrate the most mature DCQCN implementations, with ASIC-level ECN marking at line rate for all 64 ports simultaneously.
Low-Latency Topologies: Spine-Leaf and Beyond
The canonical spine-leaf topology with 100GbE or 400GbE uplinks remains the reference architecture for NVMe over RoCEv2 deployments. However, database-specific optimizations require deviation from general-purpose designs:
- Single-tier leaf-only for latency-sensitive OLTP clusters with fewer than 64 storage targets, eliminating one ASIC hop (approximately 400ns savings).
- Dual-rail RoCEv2 with active-active NIC bonding for 99.9999% availability, requiring MLAG or EVPN-MH configuration on leaf pairs.
- PFC deadlock avoidance via lossless queue separation—dedicating Priority 3 exclusively to RoCEv2 traffic and Priority 0 to management, with no shared buffer pools.
- Jumbo frames (9000 MTU) end-to-end to reduce packet processing overhead by 40% for large block transfers, though 4KB database I/O remains MTU-agnostic.
Thermal and Power Considerations for Dense Deployments
A 1U switch with 32x 400GbE ports dissipates 450-600W under full RoCEv2 load, requiring front-to-back airflow at 200 LFM minimum. RoHS-compliant components and 80 Plus Titanium power supplies reduce PUE impact by 8-12% compared to legacy FC director-class switches. For NEBS Level 3 environments, GR-63-CORE thermal testing validates operation up to 55°C continuous.
Verdict: Architectural Imperatives for Deterministic Database Fabrics
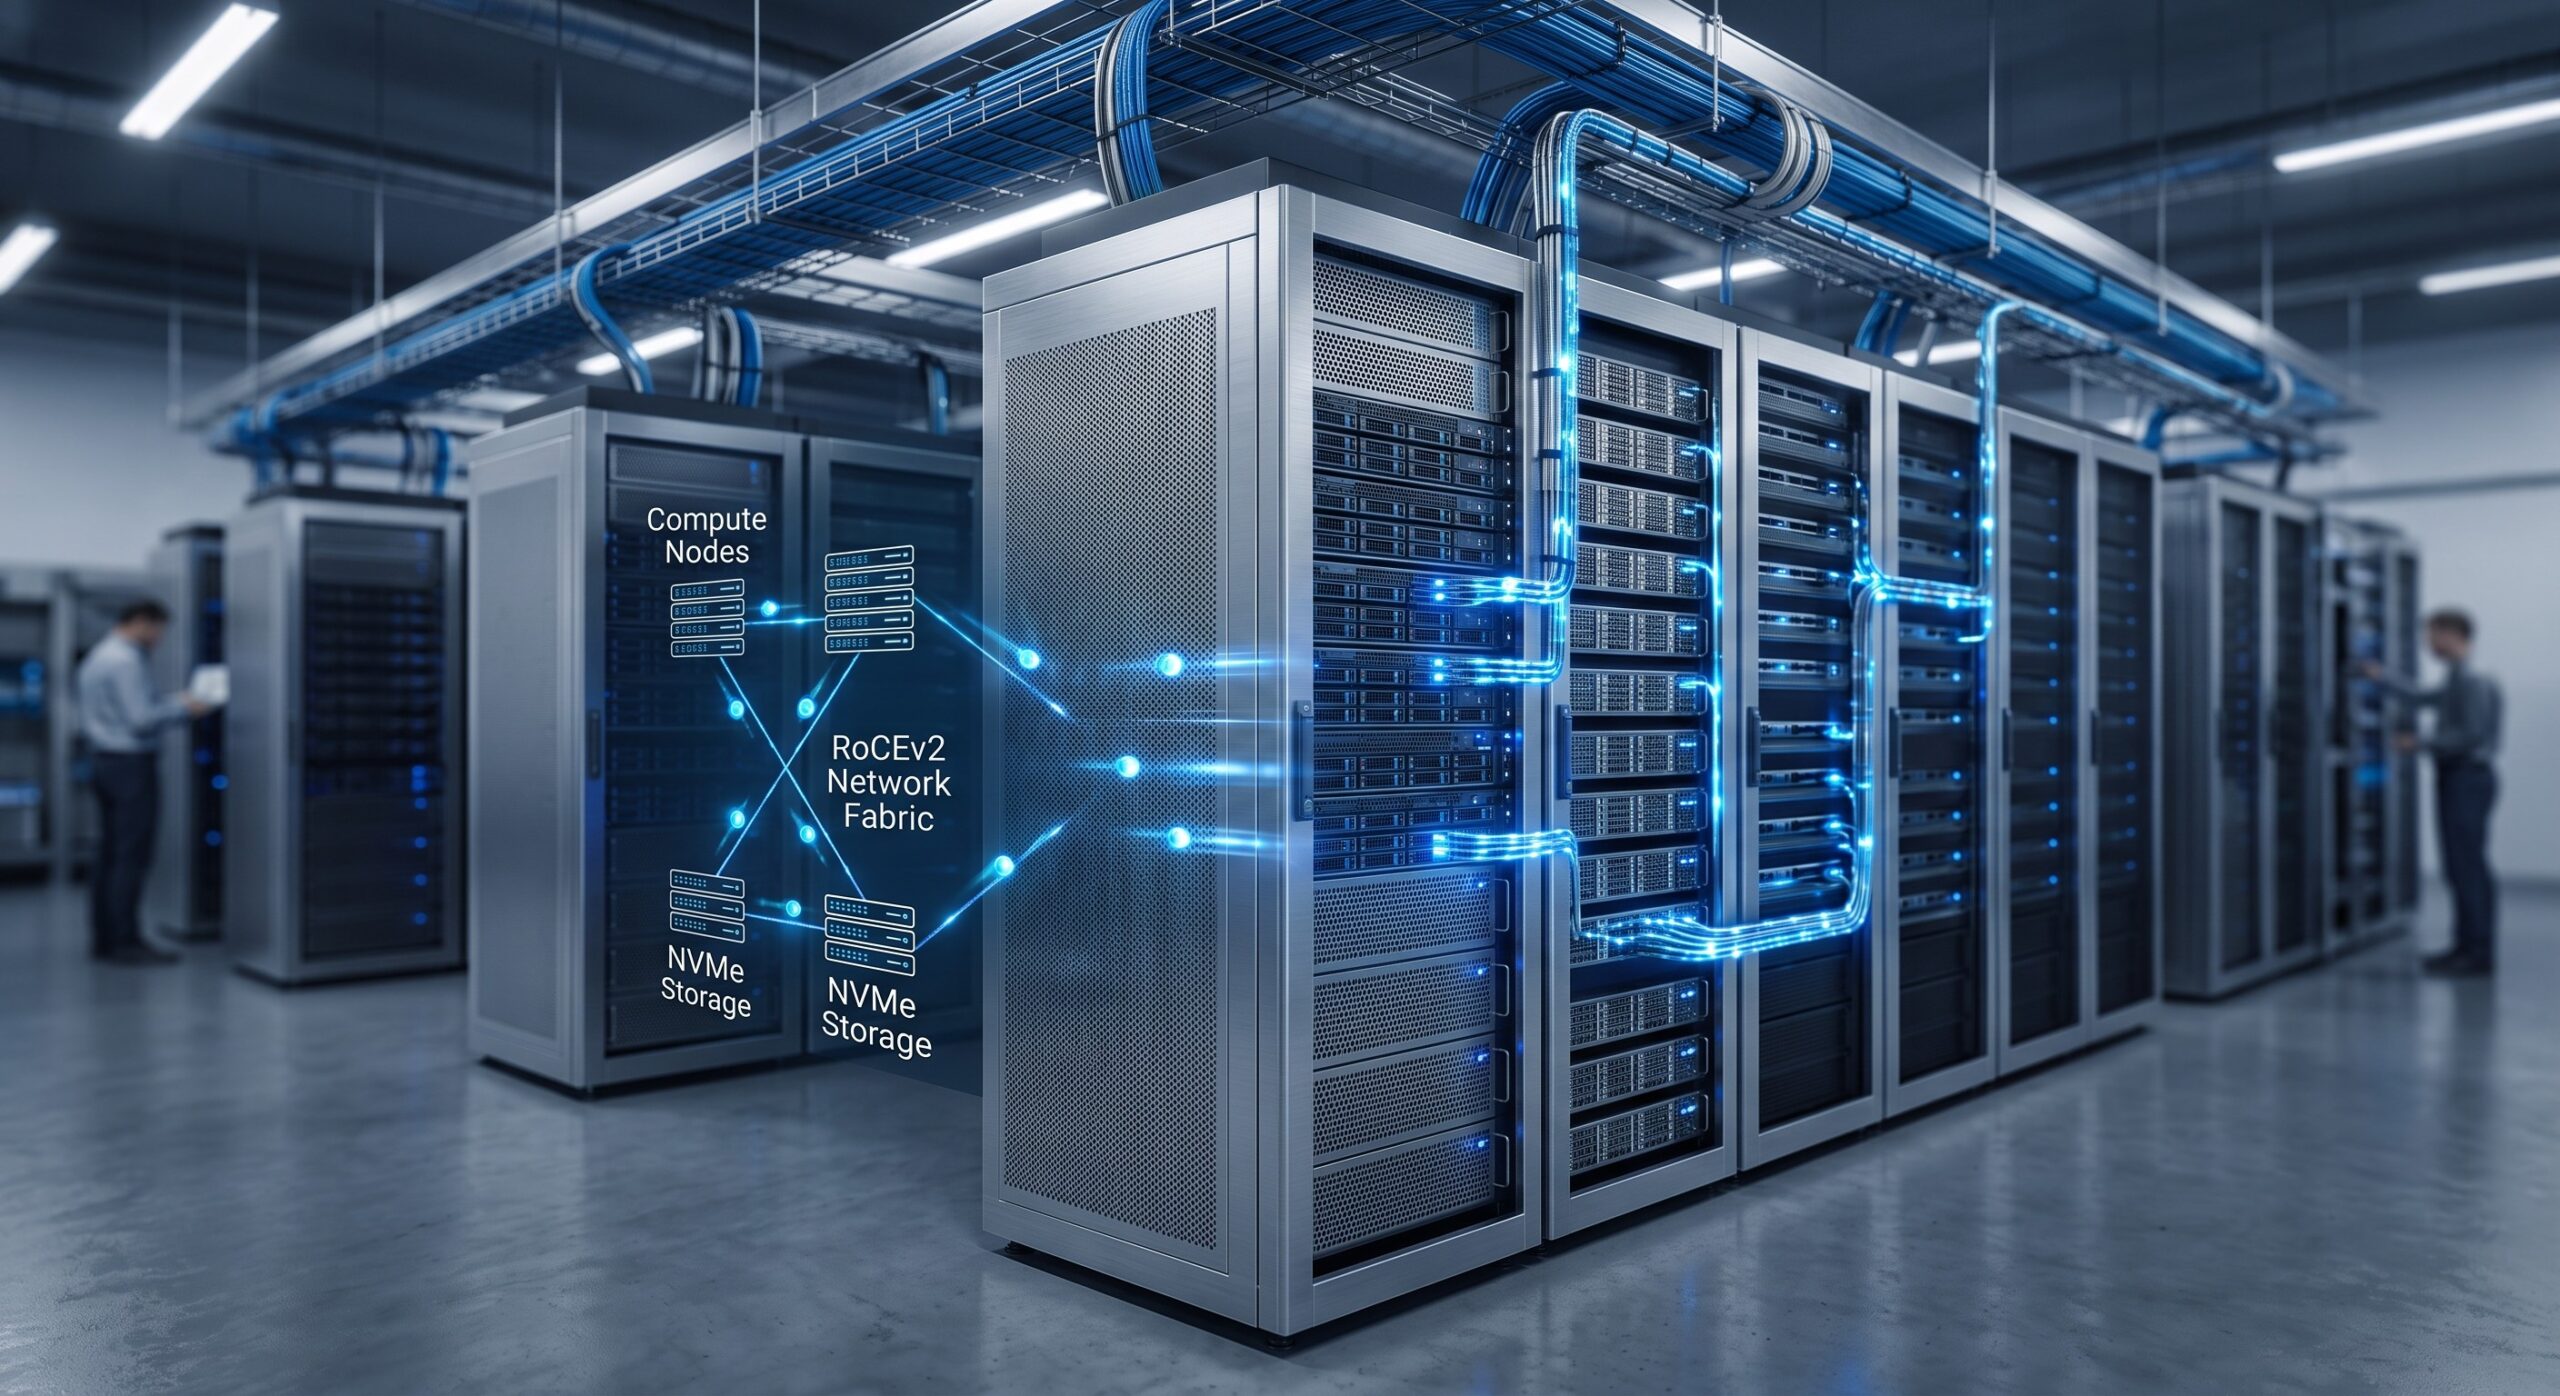
NVMe over RoCEv2 delivers transformative latency reductions for ultra-low-latency databases, but success hinges on disciplined hardware selection and ASIC-level congestion management. The packet pipeline analysis confirms that cut-through switching, PFC watchdog, and DCQCN tuning are non-negotiable prerequisites—not optional optimizations. Organizations deploying 400GbE fabrics with ConnectX-7 NICs and Spectrum-4 or Nexus 9300-FX3 switches can expect sub-100μs deterministic latency at 99.999th percentile with MTBF exceeding 1.5 million hours for the switching fabric.
As database workloads continue to push the boundaries of real-time analytics and AI/ML inference, the convergence of NVMe, RDMA, and lossless Ethernet represents the definitive path forward. Telecom hardware architects must prioritize buffer architecture, ECN granularity, and thermal design as first-class design criteria—not afterthoughts—to unlock the full potential of this transformative storage networking paradigm.
Leave a comment