
Identifying Microburst-Induced Bottlenecks in Big Data Fabrics
In high-density big data fabrics, sustained throughput is rarely the limiting factor. The real threat to application performance and SLA compliance is the microburst—a transient, sub-millisecond traffic spike that can exhaust switch packet buffers before Active Queue Management (AQM) or Priority-based Flow Control (PFC) can react. Unlike elephant flows, microbursts are invisible to standard 1-second SNMP polling and often evade conventional monitoring. The result is tail-drop packet loss, TCP retransmission storms, and latency spikes that cripple distributed storage and AI training workloads.
The challenge is not simply adding more buffer memory. Buffer bloat—oversized, deep buffers—introduces unacceptable queueing latency and destroys the deterministic performance required by RoCEv2 and NVMe-oF traffic. The engineering objective is therefore precise: size the buffer to absorb realistic microburst volumes while maintaining sub-microsecond forwarding latency under steady-state conditions.
Solving Latency via Architecture: Shared Buffer Pools and Dynamic Thresholds
The Role of Shallow Shared Buffers in Modern ASICs
Modern datacenter switching silicon, such as Broadcom’s StrataXGS Tomahawk and Trident families, employs a shallow, fully shared on-chip SRAM pool rather than external HBM or oversized discrete buffers . This architectural choice is deliberate. By keeping the buffer physically close to the packet processing pipeline, the ASIC achieves line-rate forwarding with deterministic latency—typically around 450 ns for L3 forwarding in Tomahawk-class devices—while still providing sufficient absorption capacity for ingress microbursts .
The shared buffer pool operates under dynamic threshold algorithms. Rather than allocating a fixed per-port or per-queue buffer quota, the switch ASIC dynamically calculates the available headroom based on current occupancy. When a port is idle, it can theoretically consume the entire shared pool to absorb a burst; as overall occupancy rises, per-port limits shrink to prevent one aggressive flow from starving others. This approach directly addresses the incast and concurrent microburst scenarios that characterize big data fabrics .
Why Buffer Size Alone Is a Misleading Metric
Vendors frequently advertise buffer capacity in megabytes or gigabytes, but this metric is meaningless without context. A 1 GB buffer operating at 400 Gbps introduces approximately 20 ms of queueing delay when full—a delay that triggers TCP retransmissions and defeats the purpose of low-latency fabric design . The relevant specification is not total buffer capacity, but buffer-to-bandwidth ratio and the ASIC’s ability to sustain full line-rate forwarding for minimum-sized packets without internal crossbar contention .
Research on concurrent microbursts demonstrates that a ring buffer of approximately 300 entries can handle 10 simultaneous microbursts with a packet miss rate below 1% under realistic cache traffic workloads . This finding underscores that intelligent buffer management—not raw capacity—determines microburst absorption effectiveness.
Operational Parameter Limits and Buffer Sizing Matrix
The following table summarizes the critical engineering parameters for buffer sizing in big data fabric switching, derived from current ASIC specifications and industry deployment data.
| Key Parameter | Technical Specification / Recommended Value |
|---|---|
| ASIC Buffer Architecture | Shallow shared on-chip SRAM pool (32–132 MB typical for Tomahawk/Trident class) |
| Forwarding Latency (L3) | ~450 ns at line rate for shallow-buffer ASICs |
| ECN Marking Threshold | 30–40% of shared buffer occupancy (starting point for RoCEv2 fabrics) |
| PFC XOFF Threshold | 60–70% of shared buffer occupancy (leaves headroom for transient bursts) |
| Microburst Ring Buffer (Telemetry) | 300 entries sufficient for |
| Buffer-to-Bandwidth Ratio | Avoid configurations exceeding ~5 ms of queueing delay at full occupancy |
| Monitoring Granularity | Microsecond-level queue watermark and buffer occupancy histograms required |
Configuration Best Practices for Microburst Mitigation
Aligning AQM and PFC with Buffer Thresholds
IETF RFC 7567 explicitly recommends that AQM mechanisms control overall queue sizes “to ensure that arriving bursts can be accommodated without dropping packets” . In practice, this means configuring Explicit Congestion Notification (ECN) marking thresholds well below the physical buffer limit. A conservative starting point for RoCEv2 fabrics is to set ECN marking at 30–40% of the shared buffer occupancy, with PFC XOFF thresholds at 60–70%. This leaves a dedicated headroom reserve for transient microbursts that arrive faster than the AQM control loop can signal.
Queue Placement and Traffic Isolation
Not all traffic requires the same buffer allocation. Lossless traffic classes (RDMA, FCoE) must be mapped to queues with guaranteed headroom and PFC protection. Lossy best-effort traffic can share a smaller, dynamically managed pool with more aggressive ECN marking. In big data fabrics carrying a mix of AI training and storage replication flows, isolating these classes prevents a microburst in one domain from consuming buffer resources needed by the other.
Monitoring for Microburst Events
Traditional sFlow or SNMP counters are insufficient for detecting microbursts. Deploy hardware timestamping and per-queue watermark telemetry at microsecond granularity. Many modern ASICs expose buffer occupancy histograms that reveal the frequency and duration of near-exhaustion events. If the 95th percentile queue depth consistently exceeds 50% of the configured ECN threshold during known bursty periods, the buffer allocation or threshold configuration requires reassessment.
Field Deployment Topologies: From Spine-Leaf to AI Backend
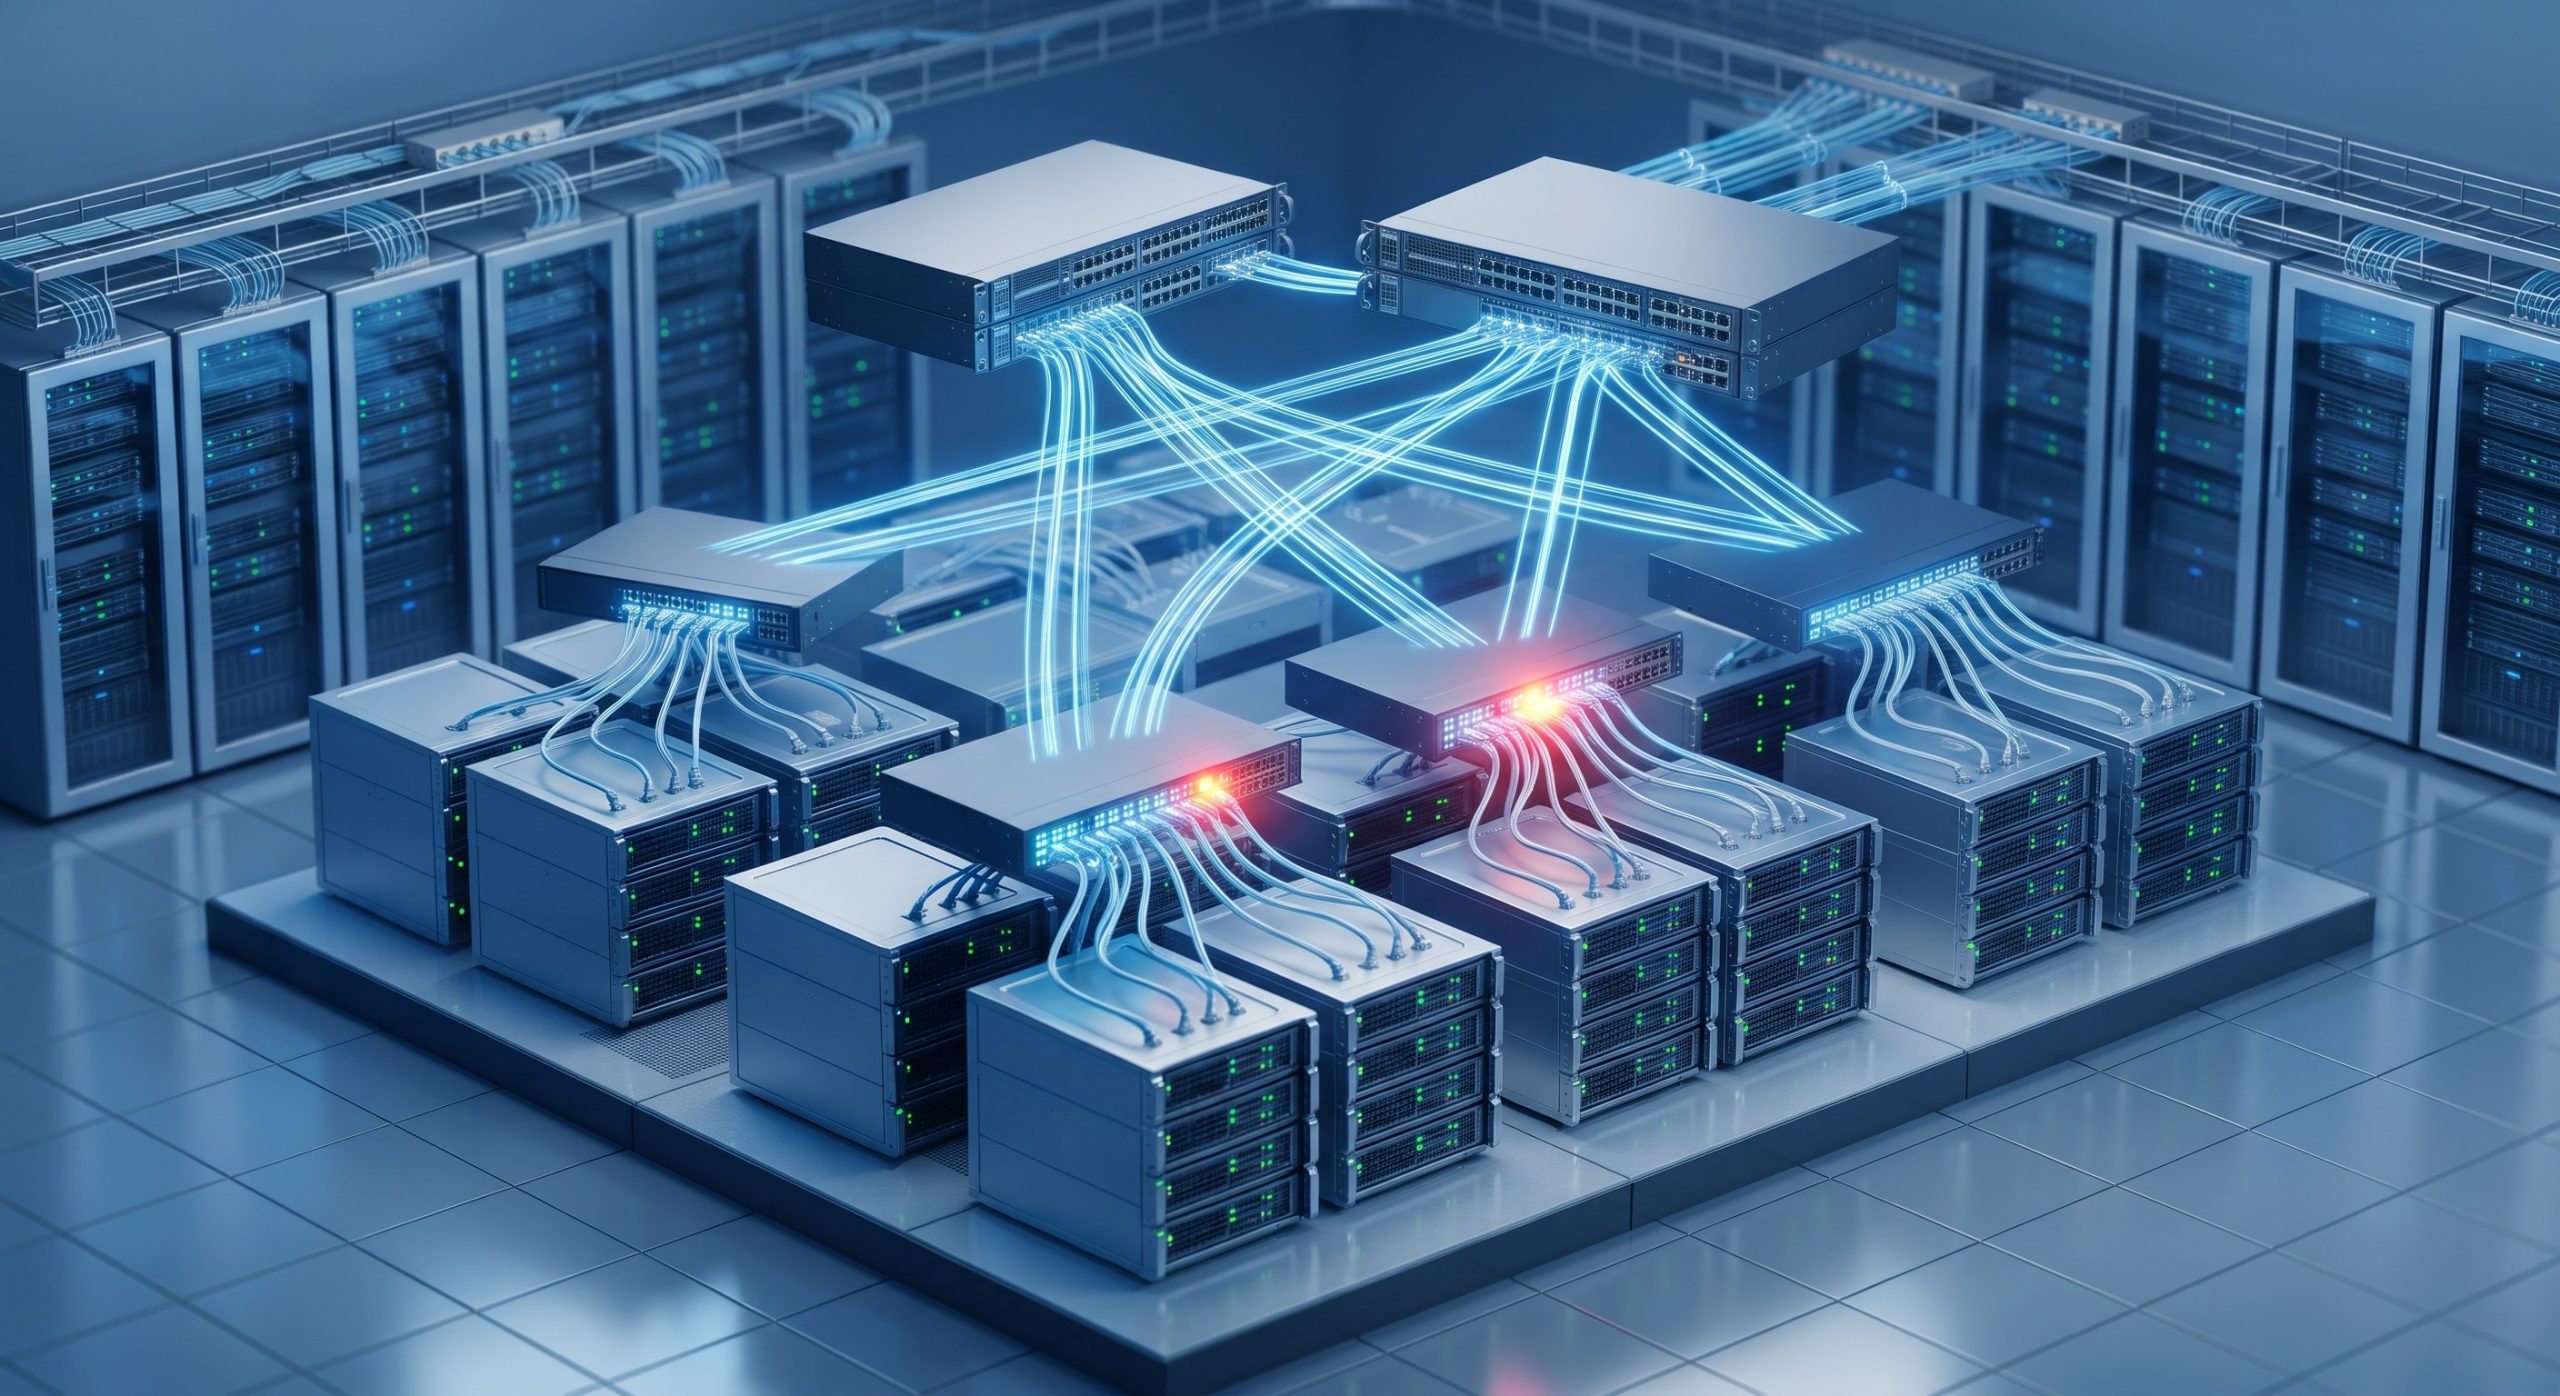
In a standard spine-leaf topology, microburst pressure concentrates at the leaf uplinks where multiple server ingress ports converge. A common failure mode is oversubscription at the leaf: if 32 × 100 Gbps server ports map to 4 × 400 Gbps uplinks (1.6:1 oversubscription), a synchronized burst from storage nodes can instantaneously saturate the uplink buffer. Deploying shallow-buffer, high-radix leaf switches with dynamic threshold buffer allocation ensures that idle server ports contribute their unused buffer quota to the congested uplink pool .
For AI backend fabrics utilizing RoCEv2, the buffer sizing challenge intensifies. Collective operations (All-Reduce, All-to-All) generate highly synchronized incast patterns across hundreds of GPU nodes. In these deployments, buffer headroom must account for the round-trip time of congestion signaling between endpoints. A fabric with 100 μs RTT requires sufficient buffer to absorb at least one bandwidth-delay product worth of burst traffic at the congestion point—not the full BDP, but a carefully tuned fraction that balances absorption capacity against latency .
Summary: The Buffer Sizing Verdict for Big Data Fabrics
Microburst traffic buffer sizing is not a problem of capacity; it is a problem of architecture, telemetry, and threshold engineering. The evidence from both academic research and production ASIC design converges on a clear verdict: shallow, shared, dynamically managed buffers outperform deep, static allocations for latency-sensitive big data workloads . Deep buffers mask underlying forwarding inefficiencies and introduce queueing delays that violate the tight SLAs of modern distributed applications.
For network architects and systems integrators, the operational mandate is threefold. First, validate that the switching ASIC sustains full line-rate forwarding for minimum-sized packets without relying on buffer absorption to hide crossbar limitations. Second, configure ECN and PFC thresholds with intentional headroom—typically 30–40% for ECN and 60–70% for PFC XOFF—to accommodate microbursts without triggering unnecessary congestion signaling. Third, deploy microsecond-granularity telemetry to observe actual buffer occupancy patterns and adjust thresholds based on measured burst characteristics, not vendor marketing specifications. When these three practices align, the fabric achieves the dual objective that defines carrier-grade big data networking: zero packet loss under burst conditions and deterministic, sub-microsecond forwarding latency under steady state.

Leave a comment